DAO Proposals & Community
View active proposals, submit new ideas, and connect with the SWARMS community.
Closes #2514 **What is wrong.** `GroupChat._collect_bids` sends every agent's bid through `asyncio.to_thread`, which runs on the loop's default executor of `min(32, os.cpu_count() + 4)` workers. A chat with more agents than that collects each turn's bids in waves, so every turn waits for at least one extra model call. Measured on master and on this branch, on a 10-core machine (14 default workers), with each bid stubbed to take 0.2 s, one turn: | Agents | Master | Bids in flight | This PR | Bids in flight | |---|---|---|---|---| | 8 | 0.216 s | 8 | 0.209 s | 8 | | 20 | 0.427 s | 14 | 0.203 s | 20 | | 32 | 0.627 s | 14 | 0.208 s | 32 | | 40 | 0.625 s | 14 | 0.423 s | 32 | **What changed.** The first statement of `_run_async` gives the run's event loop a default executor of `min(len(agents), MAX_CONCURRENT_AGENTS)` workers, reusing the constant from ConcurrentWorkflow (32). `_collect_bids` is unchanged. Its `asyncio.to_thread` calls now land on that pool. I did this instead of the `loop.run_in_executor` the issue suggests, for two reasons: - `asyncio.to_thread` copies the caller's contextvars into the worker, so each agent's OpenTelemetry spans stay under the `GroupChat.run` trace. A bare `run_in_executor` loses that unless the pool is a `ContextThreadPoolExecutor`. It would also mean passing the pool through `run`, `_run_async` and `_collect_bids`. - `asyncio.run` already calls `loop.shutdown_default_executor()` on exit, so the pool is created once per run and shut down when the run ends with no extra code. In the measurement above, the thread count is back to its baseline (4) after every run. `_run_async` is private and is only awaited inside the `asyncio.run` in `run()`, so the loop it configures is always that run's own new loop. I used `len(self.agents or ())` instead of `len(self.agents)` because `self.agents` is typed `Optional[List[Agent]]`. Pyre flags `len()` on it: I ran pyre-check locally, and the plain form adds `Incompatible parameter type [6]` on that line while this form adds nothing. `__init__` already rejects fewer than two agents, so the empty case can't happen at runtime. **Verification** - New test in `tests/structs/test_groupchat.py`: 32 scripted agents each wait on a `threading.Barrier(32, timeout=5)` inside `run`, so it passes only if every bid is in flight at once. It uses a barrier rather than wall-clock timing so CI load can't make it flaky. - With `groupchat.py` reverted to master, it fails: `assert not True where True = <threading.Barrier at 0x10f67c590: broken>.broken` - With the fix, it passes. - I also drove real `swarms.Agent`s against a local OpenAI-compatible stub server (0.2 s per completion, two bid turns). Per turn, 20 agents went from 0.705 s to 0.362 s and 32 agents from 1.028 s to 0.379 s. All 20 of 20 `agent.run` spans were parented to the `GroupChat.run` span, both before and after the change. The thread count stayed flat across 10 sequential runs. - `pytest tests/structs/test_groupchat.py -q`: 42 passed - `black . --check`: 1019 files would be left unchanged <details><summary>Measurement script</summary> ```python import threading, time from swarms.structs.groupchat import GroupChat, RESPOND_TOOL lock = threading.Lock() state = {"now": 0, "peak": 0} class SlowAgent: def __init__(self, name): self.agent_name = name self.tools_list_dictionary = [RESPOND_TOOL] def run(self, task=None, *args, **kwargs): with lock: state["now"] += 1 state["peak"] = max(state["peak"], state["now"]) time.sleep(0.2) with lock: state["now"] -= 1 return [] for n in (8, 20, 32, 40): state.update(now=0, peak=0) chat = GroupChat(agents=[SlowAgent(f"a{i}") for i in range(n)]) start = time.perf_counter() chat.run("hi") print(n, f"{time.perf_counter() - start:.3f}s", state["peak"], threading.active_count()) ``` </details> **Limits** - Above 32 agents, bids still run in waves of 32. That is the existing `MAX_CONCURRENT_AGENTS` rate-limit guard, which the issue asks this to be capped at. - The new test can only fail on unfixed code where `cpu_count + 4 < 32`, which means machines with fewer than 28 cores. GitHub's hosted runners qualify. - Measured with stubbed agents only. I made no live model calls.
 Proposed by ayaangazali
## Summary Add `DynamicWorkflow`, a multi-agent structure in which a lead agent writes a plan for the task, the plan runs across many agents in phases, and the lead combines the results at the end. It is modelled on [Claude Managed Agents dynamic workflows](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration#dynamic-workflows), released in public beta on 2026-10-09. ```python from swarms import DynamicWorkflow workflow = DynamicWorkflow(model_name="claude-opus-5-5") result = workflow.run(task="Find every bug in ./src and verify each one before reporting it") ``` ## Why - **Results.** In Anthropic's test, 70 bugs were planted in a 116k-line codebase and each setup ran 3 times. A single agent found 14, 15 and 27 bugs. A workflow found 66 in each of its 3 runs ([source](https://x.com/ClaudeDevs/status/2108591330129523146)). - **Scale.** The plan can size itself to the task: one agent per file, per document or per finding. Width is decided at run time, which none of our current structures can do in one call. - **Context stays small.** Intermediate results move between phases programmatically and never pass through the lead agent's context. The lead only reads the final outputs it combines. ## How Anthropic's version works From the [Managed Agents docs](https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration#dynamic-workflows) and the [Claude Code workflows guide](https://code.claude.com/docs/en/workflows): - **The lead writes a program.** It runs many agents in phases and combines what they return. The server runs it in the background as a workflow run while the lead keeps working or ends its turn. - **Phases.** Agents within a phase run at the same time; phases run in order. The program holds the loop, the branching and the intermediate results. - **Isolated agents.** Each agent works in its own context-isolated thread. Agents are either inline (the workflow defines them and writes a system prompt for each) or predefined (agents you list, up to 20, each with its own model). - **Building blocks.** In the Claude Code version, `agent()` runs one agent, `pipeline(items, fn)` runs one agent per item, `parallel()` runs a set at once, and `phase()` groups agents under a title. An `agent()` call can take a JSON `schema` and then returns structured output. - **Limits.** - 1,000 agents per run. - 16 agents run at once by default (configurable from 1 to 256). - Up to 4,096 items in one `pipeline()` or `parallel()` call. - A "Large workflow" warning above 25 agents or a projected 1.5M tokens. - A size guideline (`small` < 5, `medium` < 10, `large` < 50 agents) tells the lead how many agents to aim for. - **Failures.** A stalled agent restarts up to 5 times. If it still fails inside `pipeline()` or `parallel()`, its slot becomes `null` and the run continues; awaited directly, the run ends with the error. - **Quality patterns.** Common plans add a phase where independent agents adversarially verify the previous phase's findings, or draft from several angles and weigh them. - **Turning it on.** One field on the agent, then a prompt asking for a workflow ([screenshot](https://x.com/ClaudeDevs/status/2108591331660468538)): ```python agent = client.beta.agents.create( name="contract-analyst", model="claude-opus-5-5", tools=[{"type": "agent_toolset_20260401"}], multiagent={"type": "multiagent_20261001"}, ) # then send: "Run a workflow: which of these 300 contracts have a change-of-control clause?" ``` ## Proposed architecture ```mermaid flowchart TD T[run task] --> L1[Lead agent writes a WorkflowPlan] L1 --> V{Validate plan} V -- invalid: errors sent back --> L1 V -- valid --> P1 subgraph P1[Phase 1: discover] A1[agent: list files<br/>structured output: files] end P1 --> P2 subgraph P2[Phase 2: audit, one agent per file] B1[agent: audit file 1] B2[agent: audit file 2] B3[agent: audit file N] end P2 --> P3 subgraph P3[Phase 3: verify, one agent per finding] C1[agent: verify finding 1] C2[agent: verify finding M] end P3 --> L2[Lead agent combines the returned outputs] L2 --> R[Final result] ``` The diagram shows the bug-hunt plan from the benchmark. The lead writes a different plan for each task, with as many phases as it needs. ### 1. Plan The lead agent receives the following: - the task; - the names and descriptions of the predefined agents, if any; - the limits (max agents, size guideline). It returns a `WorkflowPlan` through structured output. The plan is data, not code: Anthropic's lead writes JavaScript that runs in an isolated runtime, and executing model-written Python in-process is not safe. A declarative plan with data-dependent fan-out covers the same shapes (`agent`, `pipeline`, `parallel`, `phase`). ```python class InlineAgentSpec(BaseModel): name: str system_prompt: str class Step(BaseModel): id: str agent: str # a predefined agent's name or an inline agent's name prompt: str # may use {step_id} for an earlier step's output and {item} in a fan-out for_each: Optional[str] = None # "<step_id>.<field>": run one agent per item of that list output_schema: Optional[dict] = None # JSON schema; the agent returns structured output class Phase(BaseModel): title: str steps: List[Step] # steps in a phase run in parallel class WorkflowPlan(BaseModel): name: str description: str inline_agents: List[InlineAgentSpec] = [] phases: List[Phase] # phases run in order return_steps: List[str] # outputs the lead combines at the end ``` ### 2. Validate The plan is checked before any agent runs. If a check fails, the errors go back to the lead for a revised plan, up to `max_plan_attempts`. - Every `agent` exists, and inline agents are allowed if the plan uses any. - Every `{step_id}` and `for_each` reference points to an earlier phase. - `for_each` targets a field declared in that step's `output_schema`. - The static agent count is within `max_agents`. The count for a fan-out is checked again once its list is known. ### 3. Execute phases - **Order.** Phases run in order. All agents in a phase share one `ContextThreadPoolExecutor`, bounded by `max_concurrent_agents`. - **Fresh agents.** Every agent instance is new. Inline agents are built from the plan's system prompt and `worker_model_name`, and predefined agents are deep-copied, so no conversation state leaks between agents or between runs. - **Fan-out.** A `for_each` step resolves its list from the earlier step's structured output and starts one agent per item. If the list would push the run past `max_agents`, the run stops with a clear error before starting those agents. - **Failures.** - A failed agent is retried up to `max_retries`. - After that, a fan-out slot records `None` and the run continues, and the failure is listed in the result. - A failed single step ends the run with `DynamicWorkflowError`, since later phases depend on it. ### 4. Combine The lead agent receives the task, the plan and the outputs of `return_steps`, and writes the final answer. The run's `Conversation` records the plan, each phase's outputs and the answer. The return value is formatted with `history_output_formatter` like the other structures. ## API ```python class DynamicWorkflow: def __init__( self, name: str = "DynamicWorkflow", description: str = "A lead agent plans a phased multi-agent run and combines the results.", lead_agent: Optional[Agent] = None, # built from model_name when omitted model_name: str = "gpt-5.4", agents: Optional[List[Agent]] = None, # predefined agents a plan may use allow_inline_agents: bool = True, # the plan may define its own agents worker_model_name: Optional[str] = None, # model for inline agents; defaults to the lead's max_agents: int = 1000, max_concurrent_agents: int = 16, size_guideline: str = "medium", # "small" | "medium" | "large" | "unrestricted" max_retries: int = 2, max_plan_attempts: int = 3, output_type: OutputType = "final", ): ... def run(self, task: str, img: Optional[str] = None) -> Any: """Plan the task, run the plan's phases and return the combined result.""" ``` - **`run(task)`** plans, validates, executes and combines in one call. - **`last_plan`** and **`last_run`** expose the plan and every agent's output, failures and token usage for inspection. - Register it as a `SwarmRouter` swarm type `"DynamicWorkflow"`. ## How it differs from what we have | Structure | Who decides what runs | Width | Agents | |---|---|---|---| | `HierarchicalSwarm` | Director, turn by turn; results return through its context | Fixed by the agents passed in | Fixed | | `PlannerWorkerSwarm` | Planner fills a task queue; a fixed worker pool claims tasks; a judge reviews cycles | Fixed pool | Fixed | | `GraphWorkflow` | Static DAG built before `run()` | Fixed at build time (#1761 asks for dynamic fan-out) | Fixed | | `AutoSwarmBuilder` | Designs agents and picks a swarm type | Set by the chosen type | Generated | | **`DynamicWorkflow`** | **A plan the lead writes once, executed by code** | **Decided at run time, per phase** | **Inline, predefined, or both** | ## Acceptance - [ ] `swarms/structs/dynamic_workflow.py` with `DynamicWorkflow` and the plan models, exported from `swarms`. - [ ] `run(task)` plans, validates, runs phases in order with agents in parallel within a phase, fans out over a list produced at run time, and combines the results through the lead agent. - [ ] An invalid plan goes back to the lead with its errors and is never executed. - [ ] `max_agents` and `max_concurrent_agents` are enforced, and a fan-out that would exceed `max_agents` stops before it starts. - [ ] A failed fan-out agent leaves `None` and the run continues; a failed single step raises `DynamicWorkflowError`. - [ ] Predefined agents are copied per use, so two runs don't share conversation state. - [ ] `SwarmRouter` accepts `swarm_type="DynamicWorkflow"`. - [ ] Offline tests in `tests/structs/test_dynamic_workflow.py` with a scripted LLM: phase order, parallelism within a phase, data-dependent fan-out width, limits, failure handling, plan rejection and repair. - [ ] An example in `examples/multi_agent/` (the bug-hunt plan above) and a docs page. ## Out of scope for the first version - Revising the plan between phases. Anthropic's runs are fixed once started and branch inside the program; a first version can do the same. - Resuming a stopped run from saved results. - Running in the background while the caller keeps working. `run()` blocks; an `arun()` can follow. ## References - Launch post and video: https://x.com/ClaudeDevs/status/2108591328732856655 ([video](https://x.com/ClaudeDevs/status/2108591328732856655/video/1)) - Benchmark, 70 planted bugs: https://x.com/ClaudeDevs/status/2108591330129523146 - Configuration, `multiagent_20261001`: https://x.com/ClaudeDevs/status/2108591331660468538 - Getting started and token-use advice: https://x.com/ClaudeDevs/status/2108591334449684643 - Managed Agents, multiagent orchestration: https://platform.claude.com/docs/en/managed-agents/multiagent-orchestration#dynamic-workflows - Managed Agents, workflow runs (events, interrupts, limits): https://platform.claude.com/docs/en/managed-agents/workflow-runs - Managed Agents, session budgets: https://platform.claude.com/docs/en/managed-agents/budgets - Claude Code, dynamic workflows (script API, limits, failure handling): https://code.claude.com/docs/en/workflows - Agent quickstart templates: https://platform.claude.com/agent-quickstart - Related: #1761 (dynamic fan-out in `GraphWorkflow`), [`planner_worker_swarm.py`](https://github.com/kyegomez/swarms/blob/master/swarms/structs/planner_worker_swarm.py), [`hiearchical_swarm.py`](https://github.com/kyegomez/swarms/blob/master/swarms/structs/hiearchical_swarm.py)
 Proposed by kyegomez
`MajorityVoting(verbose=False)` currently prints an initialization panel and responses from its default consensus agent. Keep initialization quiet when verbose is disabled and pass verbose through as the consensus agent's default `print_on`, while preserving an explicit `additional_consensus_agent_kwargs["print_on"]` override. Fixes #2518. ### Validation - Added four offline regression cases using real agents with deterministic local LLMs. They cover quiet/verbose initialization and consensus output, plus explicit `print_on` overrides in both directions. Before the implementation change: 1 failed, 3 passed. - Relevant MajorityVoting tests: **8 passed, 5 deselected**, including existing context and validation coverage. ```sh SWARMS_TELEMETRY_ON=false LITELLM_LOCAL_MODEL_COST_MAP=True pytest tests/structs/test_majority_voting.py -k "verbose or print_on or typed_turns or answers_not_transcripts or prior_consensus or error_handling" -q ``` - Repository-wide `black . --check` (Black 24.2.0): **1,019 files unchanged**. - Repository-wide `ruff check .` (Ruff 0.2.1) and `git diff --check`: **passed**. - Full suite attempted with `pytest tests/ -q --maxfail=1`: **74 passed, 1 failed**. The failure is `TestAgentErrorHierarchy.test_importable_from_schemas_and_structs_agent_same_object[AgentError]`, because `swarms.structs.agent` does not export `AgentError`. The same test fails identically in a clean worktree at upstream `dff4c37`. No additional dependencies. Implementation and tests were prepared with Codex assistance; validation above was executed locally on Python 3.13.6 / Windows.
 Proposed by ZedingZhang
## Summary An `llm=` object passed to `Agent` is kept for `max_loops=1`, but in autonomous mode it is silently thrown away and replaced by a `LiteLLM` client built from the agent's `model_name`. The caller's model is then never called. Requests go to whichever provider `model_name` points at, using whatever API key is in the environment, and nothing tells the caller. - **`max_loops=1`:** `Agent.__init__` keeps the caller's object ([agent.py#L415](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/agent.py#L415)) and builds a client only when none was given ([#L654](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/agent.py#L654)). - **`max_loops="auto"`:** the autonomous loop rebuilds the client whenever `agent.llm` is set ([autonomous_loop.py#L380-L381](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/agents/autonomous_loop.py#L380-L381) and [#L640-L641](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/agents/autonomous_loop.py#L640-L641)), so the caller's object is replaced on the first run. - **`dynamic_tools=True`:** `tool_search` does the same after loading new tools ([tool_manager.py#L429](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/agents/tool_manager.py#L429)), so this happens even without autonomous mode. ## Reproduction Offline. The model call is stubbed, so the script only checks which object `agent.llm` holds after a run. ```python class MyLLM: def run(self, task=None, **kwargs): return "ok" custom = MyLLM() agent = Agent(agent_name="A", model_name="gpt-5.4-mini", llm=custom, max_loops="auto") # script call_llm with create_plan -> subtask_done -> complete_task, then: agent.run("task") agent.llm is custom # False on master: it is now a LiteLLM ``` | `max_loops` | Is `agent.llm` still the caller's object after `run()`? | |---|---| | `1` | Yes | | `"auto"` | No, it is now a `LiteLLM` | ## Why simply keeping it doesn't work The autonomous loop gives the model its planning tools (`create_plan`, `subtask_done`, `complete_task` and the rest) by building them into the `LiteLLM` client. `build` puts them in the client's configuration ([llm_manager.py#L276](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/agents/llm_manager.py#L276)). Each call then hands the client only the task and the messages ([llm_manager.py#L630-L635](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/agents/llm_manager.py#L630-L635)). A custom `llm` would therefore never see the planning tools, and planning would fail with "Failed to create plan after maximum attempts". The replacement is what makes autonomous mode work today. The problem is that it happens without telling the caller. ## Options 1. **Keep the replacement and say so.** Log a warning once per agent that names the caller's object and the model that will be used instead. 2. **Refuse the combination.** Raise a clear error when `llm=` is passed with `max_loops="auto"` or `dynamic_tools=True`, explaining that these modes need a client built by swarms. 3. **Pass the tools on every call.** Hand the tool schemas to `agent.llm.run` with each request, so a custom client that accepts them can take part. This is a larger change to the client contract, and custom clients without tool support would still need option 1 or 2. Option 2 is the safest default, because it never sends requests to a provider the caller didn't choose. Option 1 keeps existing code running. ## Acceptance - [ ] An agent constructed with `llm=` never ends up with a different client unless the caller is told: a warning (option 1) or an error at construction or run time (option 2). - [ ] This covers both the autonomous loop and the `tool_search` rebuild. - [ ] Behaviour for `max_loops=1` without dynamic tools is unchanged. - [ ] Tests in `tests/agents/test_autonomous_loop.py` and `tests/tools/test_dynamic_tool_loader.py`. Split out of #2516, which reuses the client between runs but deliberately leaves this behaviour as it is.
Proposed by kyegomez## Summary With `Conversation(token_count=True)`, `add` tokenizes each message while you wait ([conversation.py#L469-L475](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/conversation.py#L469-L475)), although the comment above it says this happens in a separate thread. The count is based on the raw content. History reads count the formatted line through `_token_count_cache` (#2477), so they never reuse it, and each message is tokenized a second time. ## Measured Messages of about 1.6 KB: | | Per add | Per 1,000 adds | |---|---|---| | `token_count=True` | 38 µs | 37.9 ms | | Default | 0.3 µs | 0.29 ms | Nothing in swarms sets `token_count=True`, so only users who opt in are affected. ## Proposal - Count lazily when `token_count` is first read, or seed `_token_count_cache` with the count `add` already made. - Fix the comment. ## Acceptance - [ ] Each message is tokenized at most once. - [ ] `message["token_count"]` keeps the same value. - [ ] A test in `tests/structs/test_conversation.py`.
Proposed by kyegomez## Summary `MajorityVoting` prints Rich panels even with `verbose=False`, its default: - **On construction:** `__init__` always prints a "Majority Voting" panel ([majority_voting.py#L187-L190](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/majority_voting.py#L187-L190)). - **On every run:** `default_consensus_agent` never sets `print_on` ([#L87-L98](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/majority_voting.py#L87-L98)), so the consensus agent prints its panel every time. ## Measured Stubbed agents that answer instantly, time per run: | Voters | With printing | With `print_on=False` | |---|---|---| | 5 | 0.59 ms | 0.39 ms | | 50 | 3.33 ms | 2.87 ms | That's 0.2 to 0.5 ms per run, plus output nobody asked for. ## Proposal - Print the init panel only when `self.verbose` is set. - Pass `print_on=verbose` to `default_consensus_agent`, unless the caller passed `print_on` themselves. ## Acceptance - [ ] With `verbose=False`, constructing and running `MajorityVoting` prints nothing. - [ ] With `verbose=True`, the panels appear as they do today. - [ ] A test in `tests/structs/test_majority_voting.py`.
Proposed by kyegomez## Summary With `Agent(autosave=True)`, `_autosave_config_step` runs at the start of every loop and again after every successful step ([agent.py#L1122-L1124](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/agent.py#L1122-L1124), [#L1250-L1253](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/agent.py#L1250-L1253)), and also at the points listed under Where. Each call does the following: - it calls `workspace.save_config` ([workspace_manager.py#L346-L387](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/utils/workspace_manager.py#L346-L387)); - that serializes `Agent.to_dict()`, which includes `short_memory`, the whole conversation; - the result is written to `config.json` with `json.dump(indent=2)`. So each loop rewrites the full history about twice, and the cost of a run grows with the square of its length. CLAUDE.md recommends `autosave=True` for long autonomous runs, which are exactly the runs with long histories. ## Measured | Conversation in memory | One `_autosave_config_step` | `config.json` | |---|---|---| | empty | 0.35 ms | | | 1,000 messages | 8.16 ms | 1.91 MB | ## Where All in `swarms/structs/agent.py`: - `_autosave_config_step`: [#L1413](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/agent.py#L1413) - callers: L1111, L1124, L1251, L1304, L1394, L1408, L1445, L2771 ## Proposal - Leave `short_memory` out of the config snapshot. - Store the conversation in its own file, appending messages as they arrive. - Write the snapshot at most once per loop. ## Acceptance - [ ] The cost of `_autosave_config_step` does not grow with the conversation. - [ ] An autosaved agent can still be restored with its conversation. - [ ] Tests in `tests/structs/test_agent.py`.
Proposed by kyegomez## Summary `GroupChat._collect_bids` asks every agent whether it wants to speak, running each request through `asyncio.to_thread` ([groupchat.py#L411-L418](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/groupchat.py#L411-L418)). `to_thread` uses the event loop's default executor, which has `min(32, os.cpu_count() + 4)` workers. With more agents than that, the requests run in waves, so every turn costs at least one extra model call's worth of time. `run()` also calls `asyncio.run` ([groupchat.py#L560](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/groupchat.py#L560)), which creates a new loop and executor on every run. ## Measured 20 agents, each request stubbed to take 0.2 s, on a 12-core machine (16 default workers), one turn: | | Time | |---|---| | Now | 0.411 s | | Ideal | 0.2 s | ## Proposal - Run the requests on a `ThreadPoolExecutor` sized to `len(self.agents)` and capped at `MAX_CONCURRENT_AGENTS`, like ConcurrentWorkflow ([concurrent_workflow.py#L25](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/concurrent_workflow.py#L25)). - Submit them with `loop.run_in_executor`. - Create the pool once per run and shut it down when the run ends. ## Acceptance - [ ] One turn with 20 agents whose requests take 0.2 s finishes in about 0.2 s. - [ ] The pool is shut down when the run ends. - [ ] A test in `tests/structs/` that uses a stubbed request.
Proposed by kyegomez## Summary With `Conversation(autosave=True)`, every `add` rewrites the whole history file, so the cost of a run grows with the square of its length. - **Every add saves the whole file.** `add` calls `_autosave()` ([conversation.py#L574-L577](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/conversation.py#L574-L577)), and `export()` writes the full history with `save_as_json` or `save_as_yaml` ([conversation.py#L905-L913](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/conversation.py#L905-L913)). - **The JSON path is the slow one.** `json.dump(f, indent=4)` can't use the C encoder, so each save makes about 3,000 small `write()` calls. - **YAML uses PyYAML's pure-Python emitter,** although libyaml is installed. - **`add_multiple_messages` saves twice.** It saves once more after `add_multiple`, which has already saved after every message ([conversation.py#L581-L589](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/conversation.py#L581-L589)). ## Measured Messages of about 1.6 KB, on bc246b8d9. **Adding messages with autosave on:** | Format | Adds | Total | Cost of one add, first 10 → last 10 | |---|---|---|---| | JSON | 1,000 | 3.04 s | 0.34 ms → 5.39 ms | | YAML | 300 | 29.5 s | 4.0 ms → 188.8 ms | The JSON run ends with a 1.9 MB file, but writes about 950 MB in total. **Saving 1,000 messages once:** | Method | Time | |---|---| | `json.dump(f, indent=4)` | 6.21 ms | | `f.write(json.dumps(..., indent=4))` | 3.80 ms | | Appending one JSONL line | 0.05 ms | | `yaml.dump` | 652 ms | | `yaml.dump(..., Dumper=yaml.CSafeDumper)` | 26.7 ms | ## Proposal - **Append instead of rewriting.** Autosave appends one line per message, and the full file is written on `export()` and on exit. Alternatively, batch the saves. - **At minimum, speed up each save:** - write with `f.write(json.dumps(...))`; - use `yaml.CSafeDumper` when available, falling back to `SafeDumper`; - remove the second save in `add_multiple_messages`. - **Keep loading working.** Whatever the format, the existing load paths must still read the saved file. ## Acceptance - [ ] The cost of one add with autosave on stays flat as the history grows. - [ ] A saved conversation loads back unchanged. - [ ] `add_multiple_messages` saves once. - [ ] Tests in `tests/structs/test_conversation.py`.
Proposed by kyegomez## Summary When a structure calls `agent.run(task, messages=...)`, `Agent.run` adds those messages to the agent's `short_memory` ([agent.py#L2694-L2697](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/agent.py#L2694-L2697)). The model request for that call is built from `messages` directly ([agent.py#L1162-L1165](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/agent.py#L1162-L1165)), not from memory. So every call stores another full copy of the shared history inside the agent, and the agent's memory grows with every call. Every structure that shares a conversation passes it this way: - AgentRearrange, and through it SequentialWorkflow and SwarmRouter; - MajorityVoting; - RoundRobin; - GroupChat; - HierarchicalSwarm; - GraphWorkflow. ## Measured Stubbed model, no network, on bc246b8d9: | Scenario | Each agent's `short_memory` | Shared conversation | |---|---|---| | RoundRobin, 4 agents, `max_loops=10`, one run | 211 to 241 messages | 41 messages | | SequentialWorkflow, 3 agents, the same workflow run 8 times | the last agent grows from 6 to 41 messages, +5 per run | | GroupChat calls every agent with the whole conversation for each message posted, so over T messages each agent stores about T²/2. ## What reads the copy - **`run()`'s own return value.** Structures discard it and use `agent_answer` instead. - **`ContextCompressor.maybe_compress`,** on every loop ([agent.py#L1119-L1120](https://github.com/kyegomez/swarms/blob/bc246b8d9/swarms/structs/agent.py#L1119-L1120)). It measures this memory. Once the memory passes 90% of `context_length`, it makes a summarizing model call on content the request doesn't use (code reading). - **Disk writes.** - With `autosave=True`, the copy is written to disk. - With `persistent_memory=True`, every copied message is also appended to MEMORY.md. - **A later `agent.run(task)` without `messages`.** That request is built from memory. ## Proposal Leave the request as it is and store less. Either: - for a call that has `messages`, add only the task and the agent's answer; or - once the answer is recorded, trim `short_memory` back to where the run started. `agent_answer` must still find the final answer in memory. This changes what `short_memory` holds after a structure runs. A later `agent.run(task)` without `messages` would then see the agent's own turns instead of the whole shared history. That needs a decision in the PR. ## Acceptance - [ ] After a RoundRobin run with 4 agents and `max_loops=10`, each agent's `short_memory` holds its own turns, not 5 to 6 times the shared conversation. - [ ] Re-running a SequentialWorkflow, or a GroupChat run, no longer adds the shared history to each agent on every call. - [ ] `agent_answer` returns the same answers as before in every structure. - [ ] Tests in `tests/structs/test_agent.py`.
Proposed by kyegomez## Summary [RouteHub](https://github.com/The-Swarm-Corporation/RouteHub) (`routehub` on PyPI, 0.1.0) is the Swarms LLM gateway. It keeps litellm's function names and is built on the official OpenAI SDK. This issue adds it as an optional backend: - `pip install "swarms[fast]"` installs RouteHub, and swarms then makes every model call through it instead of litellm. - A plain `pip install swarms` keeps litellm and behaves exactly as today. ## Why - **Import time.** On master (f836dcb56, Python 3.13, 3 runs), `import swarms` takes 1.1 to 1.9 s, and litellm accounts for 0.9 to 1.3 s of that: 795 of the 3,306 modules loaded. RouteHub's own benchmark puts its import at 5.5 ms. This matters most for the CLI, short-lived agent processes, serverless and tests. - **Overhead per call.** RouteHub reports 0.004 ms per call, against litellm's 0.74 ms. - **Supply chain.** RouteHub has three direct dependencies (`openai`, `pydantic` and `tiktoken`) and 20 installed packages in total, against litellm's 58. litellm is pinned at 1.76.1 since its supply-chain incident, and that pin is the source of all 22 Docker Scout findings left in `swarmscorp/swarms`. - **No global state.** `LiteLLM.__init__` sets `litellm.set_verbose`, `ssl_verify`, `num_retries` and `drop_params` as module globals (`swarms/utils/litellm_wrapper.py:386-394`). So the agent constructed last decides them for every agent in the process. RouteHub takes all four as arguments to each call. ## Proposal - **Add a `fast` extra** in `pyproject.toml`. `routehub[fast]` also brings in orjson. ```toml [tool.poetry.dependencies] routehub = { version = ">=0.1.0", extras = ["fast"], optional = true } [tool.poetry.extras] fast = ["routehub"] ``` - **Choose the backend in one module**, for example `swarms/utils/llm_backend.py`: - It imports RouteHub when it is installed and litellm otherwise, and re-exports the names in the table below. - Every file in that table imports from this module instead of from `litellm`. - `SWARMS_LLM_BACKEND=litellm` forces litellm even when RouteHub is installed, as an escape hatch. - **Don't import litellm when RouteHub is selected.** If `import swarms` still imports litellm, the import-time gain is lost. - **Keep the public names.** `swarms.utils.LiteLLM` and `LiteLLMException` are exported, so they stay. Only the backend underneath them changes. ## Code that needs to change RouteHub provides every one of these names (`routehub/__init__.py`). | File | litellm names it uses | |---|---| | `swarms/utils/litellm_wrapper.py` | `completion`, `acompletion`, `supports_vision`, `supports_reasoning`, plus the four globals above | | `swarms/structs/agent.py` | `model_list`; `AuthenticationError`, `BadRequestError`, `InternalServerError`; `get_max_tokens`, `get_model_info`, `supports_function_calling` | | `swarms/agents/llm_manager.py` | `AuthenticationError`, `BadRequestError`, `InternalServerError`; `supports_function_calling`, `supports_parallel_function_calling`, `supports_vision` | | `swarms/agents/context_compressor.py` | `completion` | | `swarms/utils/get_reasoning_efforts.py` | `completion` | | `swarms/utils/litellm_tokenizer.py` | `encode`, `model_list` | | `swarms/cli/models.py` | `model_list`, `get_model_info` | | `swarms/structs/tree_swarm.py`, `swarms/structs/agent_router.py` | `embedding` | | `swarms/structs/check_models.py`, `swarms/structs/agent_loader.py` | `model_list` | | `swarms/cli/main.py:28` | `traceback`. This is the standard library module, re-exported by litellm. It should be a plain `import traceback` either way. | ## Differences to handle These come from RouteHub's [migration notes](https://github.com/The-Swarm-Corporation/RouteHub#migrating-from-litellm). - **Response objects.** RouteHub returns the OpenAI SDK's `ChatCompletion` and `ChatCompletionChunk`, which don't support dictionary access such as `response["choices"]`. litellm's `ModelResponse` does, so the wrapper's response and stream parsing needs an audit. - **Settings per call.** The four globals become arguments to each `completion` call. - **`max_tokens`** is sent to OpenAI as `max_completion_tokens`. - **Model catalog.** RouteHub's `model_list`, `get_model_info` and `get_max_tokens` read OpenRouter's live model list on first use, where litellm reads its own bundled table. This has three effects: - `Agent.__init__` calls `get_model_info` (`_default_context_length`, `_default_max_tokens`), so constructing the first agent now makes that fetch. - Agent construction must still work offline. It falls back today when the call raises, and that needs to hold with RouteHub too. - `swarms models` will list a different set of models. - **Exceptions.** RouteHub's exception classes subclass the OpenAI SDK's, not litellm's. The `except` clauses in `agent.py` and `llm_manager.py` must catch RouteHub's when it is selected. - **Ignored arguments.** RouteHub accepts `caching`, which the wrapper passes at `litellm_wrapper.py:1270`, and ignores it. ## Not in scope - **Making litellm itself optional.** An extra can't remove a required dependency, so `swarms[fast]` still installs litellm and simply never imports it. Dropping litellm from the base install would clear the 22 Scout findings, and is a follow-up once RouteHub has proven itself. ## Acceptance - [ ] `pip install swarms` behaves as it does today, on litellm. - [ ] With `swarms[fast]`, `litellm` is not in `sys.modules` after `import swarms`. - [ ] With `swarms[fast]`, real calls work through RouteHub: - [ ] `run` and `arun`; - [ ] streaming and tool calling; - [ ] images; - [ ] `reasoning_effort` and Claude thinking; - [ ] structured output; - [ ] embeddings and token counting; - [ ] `swarms models`. - [ ] With RouteHub, an agent can be constructed offline. - [ ] `SWARMS_LLM_BACKEND=litellm` selects litellm while RouteHub is installed. - [ ] The test suite runs against both backends, with no new failures against a master baseline. - [ ] The PR states the `import swarms` time before and after. - [ ] The README and docs describe `swarms[fast]`.
Proposed by kyegomez## Summary With `opentelemetry-exporter-otlp-proto-http` 1.45, telemetry exports skip `CompressingSession`. Spans go out uncompressed, with no `Content-Encoding` header, so #2506's zstd compression silently does nothing. 1.45.1 is what a fresh install resolves to, because `pyproject.toml` allows any version (`opentelemetry-exporter-otlp-proto-http = "*"`). Environments that still have an older exporter, such as 1.30.0, compress correctly, which is why this wasn't caught. **Who is affected:** - **Every new `pip install swarms`,** on any Python version. I saw it on both 3.13 and 3.14. - **Every Docker image built from scratch.** A `python:3.13-slim` image with swarms installed gets 1.45.1. ## Cause `swarms/telemetry/compression.py` overrides only `CompressingSession.post()`. The two exporter versions send differently: | Exporter | How it sends | Goes through our compression? | |---|---|---| | 1.30.0 | `session.post(...)` | yes | | 1.45.1 | `RequestsHTTPTransport.request()`, which calls `session.request(method="POST", ...)` directly | no | Because we create the exporter with `compression=NoCompression` (so bodies aren't compressed twice), nothing compresses the body at all. ## Impact - **Large exports are rejected.** Spans carry full conversations and every model call's request and response (#2504, #2505), so uncompressed exports grow quickly: a 60-turn session flushed at once is 57.6 MB. The collector rejects anything over its 8 MB body cap with a 413, and that batch is lost silently. - **The biggest batches are also dropped before sending.** 1.45 adds `max_request_size`, which drops any batch whose serialized size is over 64 MiB before it's sent. The size is measured before compression, so this applies even once compression works again. ## Reproduce ```bash uv venv -p 3.13 /tmp/v && VIRTUAL_ENV=/tmp/v uv pip install . pytest pytest-asyncio /tmp/v/bin/python -m pytest \ "tests/telemetry/test_telemetry.py::TestAgentConversation::test_exports_are_zstd_compressed" ``` The test fails at `assert all(r["encoding"] == "zstd" for r in requests)`. With `opentelemetry-exporter-otlp-proto-http==1.30.0`, the same test passes. ## Proposed fix Override `request()` instead of `post()` in `CompressingSession`: - compress only `POST` requests whose body is `bytes`; - keep the existing zstd-to-gzip fallback; - send through `super().request()`. `requests.Session.post()` calls `self.request()` internally, so this one override covers both exporter generations. I tried this on a scratch copy. `tests/telemetry` gives 209 passed and 0 failed with both exporter 1.30.0 (Python 3.12) and 1.45.1 (Python 3.14), including `test_exports_are_zstd_compressed`. black and ruff are clean. **Worth deciding separately:** whether to pass `max_request_size` when the installed exporter supports it, so the 64 MiB pre-compression limit doesn't drop large batches. The parameter doesn't exist in older exporters, so it can't be passed unconditionally.
Proposed by kyegomezPart of #2496 `DecisionModel._arequest` opened a new `httpx.AsyncClient` for every call. So every `arun` made a new TCP connection, plus a TLS handshake against a real provider, even inside an `asyncio.gather` over many calls. The code comment explained why: a shared client breaks once `asyncio.run` closes its event loop. ## What changed - **One cached client per loop.** Async clients are now cached per running event loop, in a `weakref.WeakKeyDictionary` keyed by the loop. Calls on the same loop share one client and its connection pool, and a later `asyncio.run` gets a fresh client, which is the problem the old comment was guarding against. - **`aclose()`.** This new method closes the running loop's client. `close()` still closes the sync client, as before. - **The retry loop is unchanged.** It now uses the cached client instead of opening its own. - **One test fixture, adjusted.** It replaces the module's `asyncio` with a stub so retries don't really sleep. The stub now also passes the real `get_running_loop` through. ## Not in this PR: the aiohttp extra The issue's own text says this half needs a decision: use `httpx-aiohttp` whenever it's installed, or only when asked for. That's your call, so this PR doesn't add the extra. Connection reuse is the part the issue says matters regardless of the library underneath, and it doesn't depend on that decision. ## Benchmark `arun` calls against a local aiohttp server with 20 ms of latency, master against this branch: | | master: new client per call | this branch: one client per loop | |---|---|---| | 20 sequential calls | 20 connections, 0.030 s each | 1 connection, 0.025 s each | | 50 concurrent, 5 rounds | 250 connections, 0.160 s per round | 170 connections, 0.069 s per round | | 200 concurrent, 5 rounds | 1000 connections, 0.602 s per round | 918 connections, 0.176 s per round | This is plain HTTP on localhost. A real provider adds a TLS handshake to every new connection, so the per-call cost on master is higher there. Under bursts the connection count stays high because httpx keeps at most 20 idle connections by default. I left those limits alone. ## Tests `test_arun_reuses_one_async_client_per_event_loop`, in the existing `tests/structs/test_decision_model.py`, runs two `asyncio.run` bursts of six calls each on one model: - exactly two clients are created, one per loop; - all 12 requests are sent; - `aclose()` closes the second loop's client. It fails on master's `decision_model.py`, which creates 12 clients. All 128 tests in the file pass here. ## Verification - black and ruff are clean, and the diff adds no comments. - No new dependencies. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
 Proposed by Steve-Dusty
Fixes #2498 ## Problem `SwarmRouter._run` passes its run-time `**kwargs` to `swarm.run(...)`, which is what its docstring says. It also passes them to `_create_swarm(...)`, which hands them to the swarm's constructor. Any keyword argument meant for the run therefore breaks the build step for most swarm types: ``` router.run("hello", streaming_callback=cb) RuntimeError: Failed to create swarm ConcurrentWorkflow: ConcurrentWorkflow.__init__() got an unexpected keyword argument 'streaming_callback' ``` The same happens for AgentRearrange, MixtureOfAgents and MajorityVoting, and with `imgs=`. #2338 reported this, and #2340 fixed the `__call__` and `batch_run` paths, but this call still forwarded the kwargs. ## Change `_create_swarm` no longer receives `**kwargs`, so they reach only `swarm.run`. `*args` still go to swarm creation, as `_run`'s docstring says. This is a one-line change. ## Verification - New test `test_run_kwargs_reach_swarm_run_not_its_constructor` in `tests/structs/test_swarm_router.py`. It stubs `ConcurrentWorkflow.run` and checks that the callback passed to `router.run` reaches it. On master it fails with the constructor `TypeError` above; here it passes. - `tests/structs/test_swarm_router.py` fails the same 16 tests on master and on this branch (live-API tests), plus the new test on master. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
 Proposed by sakshamchitkara-dotcom
Fixes #2497 ## Problem `Agent._transcript_from_memory` builds each request from `short_memory` and skips every row whose role is `System`. It only means to skip the system prompt, which the LLM wrapper sends separately. But two features store their output as `System` rows, and those were dropped too: - **`persistent_memory=True`:** the MEMORY.md preamble is added as a `System` row. It was loaded into history but never sent, so the CLAUDE.md "Helios" example (a second agent with the same name asked "What is my project called?") sends just `[system prompt, user]`. - **`context_compression`** (on by default): the summary that replaces the history is a `System` row too. Once compression fires, the agent loses everything earlier in the conversation. ## Change Only the row that *is* the system prompt (`content == short_memory.system_prompt`) is skipped. Every other `System` row goes to the model, mapped like any other non-agent role. This is a 4-line change. ## Verification - New test `test_system_rows_after_the_prompt_reach_the_model` in `tests/structs/test_agent.py`. It adds a `System` memory row, captures the request, and checks that the row is sent and the system prompt is not duplicated. It fails on master and passes here. - End to end, the CLAUDE.md Helios flow with `persistent_memory=True` and a mocked model: "Helios" reaches the model in the second session. On master it doesn't; here it does. - `tests/structs/test_agent.py`, `tests/agents` and `tests/structs/test_conversation.py` fail the same 32 tests on master and on this branch (live-API tests), plus the new test on master. - This touches the same lines as #2399. Whichever lands second needs a small merge. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcom## Summary `SwarmRouter._run` passes its run-time `**kwargs` both to `swarm.run(...)` and to `_create_swarm(...)` (`swarms/structs/swarm_router.py:1025-1029`). `_create_swarm` forwards them to the swarm's constructor. `_run`'s own docstring says `**kwargs` go to `swarm.run`. As a result, any keyword argument meant for the run crashes most swarm types while the swarm is being built: ```python router = SwarmRouter(agents=agents, swarm_type="ConcurrentWorkflow") router.run("hello", streaming_callback=cb) # RuntimeError: Failed to create swarm ConcurrentWorkflow: # ConcurrentWorkflow.__init__() got an unexpected keyword argument 'streaming_callback' ``` The same happens with `imgs=None`, and with ConcurrentWorkflow, AgentRearrange, MixtureOfAgents and MajorityVoting. The swarm cache key also ignores kwargs, so where a constructor does accept one, only the first call's value is ever used. #2338 reported this crash, and #2340 fixed `__call__` and `batch_run`, but the `_create_swarm` call in `_run` still passes the kwargs on. ## Fix Stop passing `**kwargs` to `_create_swarm`, so they only reach `swarm.run`. `*args` keep going to swarm creation, as documented.
Proposed by sakshamchitkara-dotcom## Summary `Agent._transcript_from_memory` (`swarms/structs/agent.py:1525`) builds every request from `short_memory`, and it skips **every** row whose role is `System`: ```python if content is None or str(role).lower() == "system": continue ``` The intent is to skip the system prompt, because the LLM wrapper sends that separately. But other features also store their output as `System` rows, and those are dropped too: - **`persistent_memory=True`**: the MEMORY.md preamble is added with role `System` (`conversation.py:278`), so it never reaches the model. Using the example from CLAUDE.md: a second `Agent(agent_name="ProjectAssistant", persistent_memory=True)` asked "What is my project called?" sends `[system prompt, user]`. The "Helios" memory loaded into its history is not in the request. - **`context_compression`** (on by default): the compression summary is stored with `summary_role="System"` (`conversation.py:295`, called from `context_compressor.py:183`). Once compression fires, the summary that replaces the history is never sent. A reused agent then loses everything earlier in the conversation. ## Reproduction ```python from swarms import Agent agent = Agent(agent_name="Mem", model_name="gpt-5.4", max_loops=1, print_on=False) agent.short_memory.add("System", "[Persistent Memory]\nProject: Helios") seen = {} def capture(*args, **kwargs): seen["messages"] = kwargs["messages"] return "ok" agent.call_llm = capture agent.run("What is my project called?") print([m["content"][:40] for m in seen["messages"]]) ``` On master (`dd0cd364`) the request contains only the user turn. The `Project: Helios` row is missing. ## Fix Skip only the row that is the system prompt itself. Send every other `System` row to the model.
Proposed by sakshamchitkara-dotcom## Problem `DecisionModel.arun` is the one place swarms runs its own HTTP calls at high concurrency, such as the `asyncio.gather` over many `arun` calls in `examples/decision_models/decision_screening_funnel.py`. Two things slow it down: - `_arequest` opens a new `httpx.AsyncClient` for every call (`swarms/structs/decision_model.py:697`), so every request makes a new TCP connection and TLS handshake. The comment there explains why: a shared client breaks once `asyncio.run` closes its event loop. - httpx's async client is slower than aiohttp's under heavy concurrency, which is why the OpenAI and Anthropic SDKs offer an aiohttp option. This hasn't been measured for `DecisionModel` yet. ## Proposal The OpenAI and Anthropic SDKs keep httpx's API and swap in aiohttp underneath, using the `httpx-aiohttp` package (`openai[aiohttp]`, `DefaultAioHttpClient`). Do the same: - [ ] Add an optional `swarms[aiohttp]` extra that installs `httpx-aiohttp`: an optional dependency plus `[tool.poetry.extras]` in `pyproject.toml`. - [ ] When `httpx-aiohttp` is installed, `arun` uses `httpx_aiohttp.HttpxAiohttpClient`, an `httpx.AsyncClient` subclass backed by aiohttp. Otherwise it uses plain `httpx.AsyncClient`. The sync `run` stays on httpx. - [ ] Reuse one async client per event loop instead of opening one per call. Without this, every call still opens a new connection, whichever library is underneath. Key the cache on the running loop so a later `asyncio.run` gets a fresh client. Add an async close as well, since `close()` only closes the sync client. - [ ] Benchmark N concurrent `arun` calls three ways: a new client per call (today), a pooled httpx client, and a pooled aiohttp client. ## Needs a decision: use it when installed, or opt in The OpenAI SDK makes aiohttp opt-in: you pass `http_client=DefaultAioHttpClient()`. It doesn't switch just because the package is installed. If swarms switches whenever `httpx-aiohttp` is importable, installing any unrelated package that depends on it changes swarms' behaviour without anyone asking for it. In the environment below, `httpx-aiohttp` 0.1.8 is installed and nothing lists it as a requirement. An explicit option, such as a constructor argument or an environment variable, avoids that. ## Notes - aiohttp is already installed because litellm requires it. The extra only adds `httpx-aiohttp`, which requires `aiohttp>=3.10` and `httpx>=0.27`. - Tests: `tests/structs/test_decision_model.py` plugs in `httpx.MockTransport` by patching `decision_model.httpx.AsyncClient`. `HttpxAiohttpClient` uses an explicit `transport=` when one is given, so the mock still works, but the fixture has to patch whichever client class `arun` picks. - Out of scope: agent LLM calls. `Agent.arun` runs the sync `run` in a thread (`swarms/structs/agent.py:1667`), so litellm's aiohttp transport, which litellm turns on by default for async calls, is never used. That is a separate and larger change. ## Environment macOS, Python 3.12, httpx 0.28.1, aiohttp 3.14.3, httpx-aiohttp 0.1.8, swarms master at dd0cd3649.
Proposed by kyegomezFixes #2492 ## Problem If every winning agent fails, `AuctionSwarm.run` still returns normally. `successful` stays empty, the award block is skipped, and the swarm formats what is left in the conversation, which is the task and the bid summary. With `output_type="final"`, a provider outage during the work phase comes back as a "successful" run whose answer is `"Bids: A=0.9000, B=0.4000"`. No exception reaches the caller, so `SwarmRouter`'s `fallback_swarms` never fires. The only trace is a log warning. ## Change When no winner produced an answer, `run` raises `RuntimeError("[<name>] every winning agent failed")`, chained to the top-scoring winner's exception, so the real error stays visible. A run where at least one winner succeeds is unchanged, and failed winners are still skipped with a warning. The `run` docstring lists the new `Raises`. This follows the same direction as #2408, where `Agent.run` now raises after its retries run out instead of returning `''`. ## Verification - New `tests/structs/test_auction_swarm.py` (the module had no test file). It stubs the auction and the winners' execution so both winners fail, then asserts the `RuntimeError` and its `provider down` cause. On master it fails with `DID NOT RAISE` and returns the bid table. It passes here. - `black` and `ruff` are clean. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcom## Summary When every winning agent fails, `AuctionSwarm.run` (`swarms/structs/auction_swarm.py:426-455`) still returns normally. The `successful` list stays empty, the award block is skipped, and the swarm formats whatever is in the conversation. That is the user's task and the bid summary. The only sign of the failure is a log warning. With `output_type="final"`, the "answer" is the bid table. A provider outage during the work phase therefore looks like a successful run whose result is `"Bids: A=0.9000, B=0.4000"`. It also never reaches `SwarmRouter`'s `fallback_swarms`, because no exception is raised. ## Reproduction The LLM is mocked. Each agent's first call returns a valid bid, and every later call raises. ```python from swarms import Agent from swarms.structs.auction_swarm import AuctionSwarm def mk(name, conf): a = Agent(agent_name=name, model_name="gpt-4o-mini", max_loops=1, print_on=False, retry_attempts=1) calls = {"n": 0} def fake(task=None, *x, **k): calls["n"] += 1 if calls["n"] == 1: return [{"function": {"name": "bid", "arguments": '{"confidence": %s, "estimated_cost": 1.0}' % conf}}] raise RuntimeError("provider down") a.call_llm = fake a.llm_handling = lambda *x, **k: None return a print(AuctionSwarm(agents=[mk("A", 0.9), mk("B", 0.4)], output_type="final", print_on=False).run("Summarise the report")) ``` On master (`9e04ecc6`) this prints `Bids: A=0.9000, B=0.4000` and raises nothing. With `output_type="dict"`, the result holds only the user row and the bids row. ## Expected If no winner produces an answer, `run` raises, so callers and `fallback_swarms` can see the failure. If at least one winner succeeds, `run` behaves as it does today.
Proposed by sakshamchitkara-dotcomFixes #2475 ## Problem `Conversation.return_messages_as_list()` returns only `role` and `content` for each row. Any `tool_calls`, `tool_call_id` or `name` is dropped, so a run exported that way cannot be replayed against a model or used as fine-tuning data. For example, an assistant turn that called tools comes out with no record of the calls. ## Change `Conversation.to_chat_messages(include_internal=False, include_swarms_fields=False)` returns one chat-completions message per row, in order, with system rows kept. - **Tool fields:** `tool_calls`, `tool_call_id`, `name` and legacy `function_call` are carried over. Each is read from the row itself first, which is where #2399 puts them. Otherwise it is read from `row["metadata"]`, which is where `add_messages()` stores them on master today. So this works now, and keeps working after #2399 lands, without changes. - **Internal rows:** rows marked `internal` are skipped unless `include_internal=True`. - **Swarms-only fields:** `timestamp`, `message_id`, `metadata` and the rest are left out unless `include_swarms_fields=True`. - **Roles:** rows keep the role they were stored with, and there is no per-agent rewriting, which stays `to_messages`' job in #2399. - **Unchanged:** `return_messages_as_list()` is not touched. ## Verification - New test `test_to_chat_messages_keeps_tool_turns_and_round_trips` in `tests/structs/test_conversation.py`: - A conversation with a system prompt, a user turn, an assistant turn with two tool calls, their two results, and a final answer exports exactly as it was added, including `content: None` on the tool-call turn. - Passing the export back to `add_messages()` reproduces it. `time_enabled=True` on the source checks that timestamps stay out. - An internal row is skipped by default and included as a plain chat message with `include_internal=True`. - It fails on master and passes here. - `tests/structs/test_conversation.py`: 73 passed. - I did not send the export to a mocked chat-completions endpoint, the issue's third acceptance item. The test checks the request shape instead: every `tool_call_id` follows the assistant turn that made the call. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcomFixes #2478 ## Problem `import swarms` takes about 0.9s on current master. Swarms' own code accounts for very little of that; litellm accounts for 0.74s. `python -X importtime` shows two paths: - `bootup()` imports `swarms.utils.disable_logging`, which runs `swarms/utils/__init__.py`. That file imports `litellm_wrapper`, which loads litellm, and `agent_loader_markdown`, which loads `Agent`. - After `bootup()`, `swarms/__init__.py` star-imports all seven subpackages. So a program that only touches `swarms.__version__`, or a CLI that just parses arguments, pays for litellm. ## Change - **`swarms/__init__.py`:** the seven star imports are gone. The module `__getattr__` that already resolves `__version__` now loads the subpackages on first access to any other name. It loads them in the old star-import order and copies their `__all__` names into the module. `load_swarms_env()` and `bootup()` still run eagerly. - **`swarms/utils/__init__.py`:** the six names that need litellm or `Agent` (`LiteLLM`, `LiteLLMException`, `NetworkConnectionError`, `MarkdownAgentLoader`, `load_agent_from_markdown`, `load_agents_from_markdown`) now load lazily through a small module `__getattr__`. - **`swarms/structs/__init__.py`:** now starts with `from swarms import agents as agents`. The order matters because there is an import cycle that the eager star import used to hide: - `swarms.structs.agent` imports `swarms.agents.*`. - `swarms/agents/__init__.py` imports modules that import `swarms.structs.agent`. - Master works only because `swarms/__init__.py` loaded `agents` first. Without that, `from swarms.structs import Agent` in a fresh process raises `ImportError ... partially initialized module 'swarms.structs.agent'`. Loading `agents` first from `swarms.structs` keeps the same order. I did not make each subpackage `__init__.py` lazy, as the issue proposes. `import swarms` is already ~0.06s without that, and the issue's prototype shows that `from swarms import Agent` costs the same either way, because `agent.py` needs litellm. ## Compatibility Each item was checked in a fresh process against master: - `import swarms`: 0.92s on master, 0.061s here, and litellm is no longer in `sys.modules`. - `from swarms import *` produces exactly the same namespace: 168 names, identical. - `swarms.Agent is swarms.structs.agent.Agent`, and the same holds for `Conversation`, `BaseTool` and `LiteLLM`. - `swarms.structs` and the other subpackages resolve as attributes. `__version__` is in `dir(swarms)`, and an unknown attribute still raises `AttributeError`. - One visible difference: `dir(swarms)` on a fresh import lists only what has been loaded, which is `__version__`, `bootup` and `load_swarms_env`, until any export is touched. After that it lists everything again. Having `__dir__` load the subpackages itself would put the ~0.9s back on `dir()` and on tab completion. - These all import on their own: `from swarms.structs import Agent`, `swarms.structs.conversation`, `graph_workflow`, `hiearchical_swarm`, `swarms.agents.*`, `swarms.tools`, `swarms.utils.litellm_wrapper` and `swarms.cli.main`. ## Verification - New test in `tests/test___init__.py`. In a fresh process, it checks that `import swarms` does not load litellm, and that `from swarms.structs import Agent` works on its own. The first check fails on master. The second fails here if the `structs` ordering line is removed. - `tests/test___init__.py`, `tests/utils`, `tests/telemetry`, `tests/tools`, `tests/agents`, `tests/test_cli.py`, and the conversation, graph-workflow and agent suites give the same failure set on master and on this branch: 62 failed and 7 errors on both (live-API and environment tests), 1170 passed. - `black --check`, and `ruff` 0.2.1 (the CI pin), are clean. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcom## Summary `import swarms` no longer loads litellm. It now loads when the first `Agent` is built, because `Agent.__init__` looks up the model's limits in litellm's model registry. - **`swarms/utils/litellm_wrapper.py`**: module-level `completion` and `acompletion` are now thin wrappers that import litellm on first call. The names stay at module level so the ~25 tests that patch `swarms.utils.litellm_wrapper.completion` keep working. `LiteLLM.__init__` imports litellm locally for the four global settings it writes (`set_verbose`, `ssl_verify`, `num_retries`, `drop_params`). - **`swarms/structs/agent.py`, `swarms/agents/llm_manager.py`, `swarms/agents/context_compressor.py`, `swarms/structs/tree_swarm.py`, `swarms/structs/agent_router.py`, `swarms/structs/agent_loader.py`**: each litellm import moves into the function that uses it. - **Exception tuples**: `BadRequestError`, `InternalServerError` and `AuthenticationError` are removed from three `except` tuples in `agent.py` and `llm_manager.py`. Each tuple already includes `Exception`, so they catch the same errors as before. - **`swarms/structs/check_models.py`**: the `_BASE_MODELS` and `_BASE_MODEL_SET` constants, built from litellm's `model_list` at import, are replaced by a cached `_base_models()` function. - **`swarms/cli/main.py`**: `from litellm import traceback` was getting the stdlib `traceback` module through litellm. It now imports `traceback` directly. ## Timing Medians of fresh `python -c` processes on macOS with Python 3.12 and litellm 1.76.1, `SWARMS_TELEMETRY_ON=false`: | | `master` | This PR | |---|---|---| | `import swarms` | 1.83s | 0.49s | | `from swarms import Agent` | 1.91s | 0.48s | | `Agent(...)` + exit | 1.79s | 1.74s | A script that builds an `Agent` takes the same total time, because litellm still loads during `Agent.__init__`. The saving applies when swarms is imported without building an `Agent`, for example CLI startup, test collection, and tools that import swarms utilities. ## Tests - Test patches retargeted to names that moved: `tests/agents/test_context_compressor.py` (5 patches now target `litellm.completion`), `tests/structs/test_agent.py` (1 patch now targets `litellm.utils.supports_function_calling`), `tests/structs/test_check_models.py` (`_BASE_MODELS` becomes `_base_models()`), and `examples/single_agent/capabilities/streaming/test_agent_streaming_and_loop.py` (patches `litellm.supports_reasoning` instead of the module's `litellm` attribute). - The litellm-related tests ran: `tests/utils/test_litellm_*.py`, `tests/agents/test_context_compressor.py`, `tests/agents/test_llm_manager.py`, `tests/structs/test_check_models.py`, `tests/structs/test_agent_loader.py`, `tests/structs/test_agent_router.py` and `TestFunctionCallingWarning` in `tests/structs/test_agent.py`. Results: 196 passed, 15 failed. The same 15 tests fail on `master`; most are provider tests that call real APIs. - The edited example test passes. - The full test suite was not run. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by kyegomez## Problem Each time litellm is imported, it downloads its model price and context-window list (`model_prices_and_context_window.json`) from GitHub, with a 5s timeout. The fetch is in `litellm/litellm_core_utils/get_model_cost_map.py`, and setting `LITELLM_LOCAL_MODEL_COST_MAP` makes litellm use the copy bundled with the package instead. Every swarms process that creates an Agent imports litellm. Measured with litellm 1.76.1: | | Remote list (default) | `LITELLM_LOCAL_MODEL_COST_MAP=True` | |---|---|---| | `import litellm` | 1.27s | 1.13s | | Creating an Agent, then exiting (lazy-import prototype) | 1.57s | 1.44s | On a network where the request hangs instead of failing, the import can wait up to the 5s timeout. That figure comes from litellm's code; it wasn't measured here. ## Proposal In `bootup()`, set a default without overriding the user's value: ```python os.environ.setdefault("LITELLM_LOCAL_MODEL_COST_MAP", "True") ``` ## Trade-off (needs a decision) - The bundled list is frozen at the installed litellm version, so models released after it will have no context-window or pricing data. `Agent.__init__` already tolerates unmapped models (see the comment at `swarms/structs/agent.py:1863`), but defaults derived from model info would fall back. - litellm treats **any non-empty value** as on (`os.getenv("LITELLM_LOCAL_MODEL_COST_MAP", False) or ...`), so `LITELLM_LOCAL_MODEL_COST_MAP=False` does **not** opt back in to the remote list. The opt-out would be setting it to an empty string, which `setdefault` leaves alone. If we do this, the opt-out needs documenting. ## Environment macOS, Python 3.12, litellm 1.76.1, swarms master at 52db07eb3. Timings are medians of 5–7 fresh `python -c` processes. --- Related: #2478 (lazy package inits)
Proposed by kyegomez## Problem `import swarms` takes 1.8–2.1s, and swarms' own code accounts for about 0.07s of that. `swarms/__init__.py` star-imports all seven subpackages, and each subpackage `__init__.py` imports every module it exports. So the first `import swarms` loads litellm, mcp and opentelemetry even when the caller uses none of them. `python -X importtime -c "import swarms"` (cumulative): | Module | Time | Why it loads | |---|---|---| | `swarms` | 1.57s | total | | `swarms.telemetry.bootup` | 1.13s | its `from swarms.utils.disable_logging import ...` runs `swarms/utils/__init__.py`, which loads litellm through `litellm_tokenizer` | | `litellm` | 0.95s | | | `swarms.agents` | 0.44s | | | `mcp` | 0.32s | via `swarms.tools.mcp_manager` | | `swarms.telemetry` | 0.11s | opentelemetry SDK + psutil | A side effect of the same chain: `initialize_logger()` runs once before `bootup()` has set `WORKSPACE_DIR`, so the logger is configured twice. ## Proposal Replace the eager imports in each package `__init__.py` with a [PEP 562](https://peps.python.org/pep-0562/) module `__getattr__` that maps each exported name to its module and imports it on first access. The subpackage inits contain nothing but imports and `__all__`, so the name → module table can be generated from the existing import statements. Keep `load_swarms_env()` and `bootup()` eager in `swarms/__init__.py`. ## Measured with a prototype A scratch copy with lazy inits (medians of 5–7 fresh `python -c` processes): | | Current | Lazy inits | |---|---|---| | `import swarms` | 1.83–2.13s | 0.06–0.08s | | `from swarms import Agent` | 1.93–2.11s | 1.91s | Lazy inits alone barely change `from swarms import Agent`, because `swarms/structs/agent.py` imports litellm, `MCPManager` and the otel SDK at module level. The mcp and otel parts are tracked separately (see the linked issues). litellm is needed by `Agent.__init__` (`get_model_info`), so it stays. ## Compatibility - The 159 public names exported by `swarms` were identical in the prototype, and resolve to the same objects (checked `Agent`, `Conversation`, `BaseTool`, `initialize_logger`, `count_tokens`). - `from swarms import *` still loads everything, at today's cost. - `swarms.structs`, `swarms.utils`, etc. must still resolve as attributes of `swarms`. - `__dir__` should keep advertising `__version__`. ## Environment macOS, Python 3.12, litellm 1.76.1, swarms master at 52db07eb3. --- Related: #2479 (lazy mcp), #2480 (local litellm cost map), #2481 (telemetry import and exit flush)
Proposed by kyegomez## Summary There is no way to export a `Conversation` in chat-completions format without losing tool turns. `return_messages_as_list()` ([conversation.py#L1278](https://github.com/kyegomez/swarms/blob/6ba083a9e/swarms/structs/conversation.py#L1278)) returns only `{"role", "content"}` for each row. Any `tool_calls`, `tool_call_id` or `name` on the message is dropped. A run exported this way cannot be replayed against a model or used as fine-tuning data. An assistant turn that called tools, for example, comes out with no record of the calls it made. ## Depends on #2399 On `master`, there is little typed data to export yet: - Tool turns made by the agent are stored as prose. The call becomes a Python repr in assistant content, and the result comes back as a user message (see #2164). - Only messages added through `add_messages()` keep `tool_calls`, `tool_call_id` and `name`, and those are stored under `metadata` ([#L611](https://github.com/kyegomez/swarms/blob/6ba083a9e/swarms/structs/conversation.py#L611)). #2399 (closes #2386) makes these fields first-class on each row and adds `Conversation.to_messages(agent_name, start)`. That method builds the request for one agent: it leaves out system rows and internal rows, and it renders a peer agent's tool use as prose. That is right for a request, but it doesn't work as a full export. This issue covers the export, and should be built on top of #2399. ## Proposal Add an export method, such as `to_chat_messages()`, that returns every row in OpenAI chat-completions format: - Keep `system` rows, and keep rows in their original order. - On assistant rows, include `tool_calls`. On tool rows, include `tool_call_id` and `name`. Include the legacy `function_call` field if a row has one. - Skip `internal` bookkeeping rows by default, with a flag to include them. - Leave out swarms-only fields (`timestamp`, `message_id`, `metadata`) by default, with a flag to keep them. - Use one view for the whole conversation, with no per-agent rewriting. That is `to_messages`' job. Leave `return_messages_as_list()` unchanged. Callers that send its output straight to a model would start sending `tool_calls`, and the API rejects those unless matching tool results follow them. ## Acceptance - [ ] A conversation that holds an assistant turn with two tool calls and their two results exports with `tool_calls` and the matching `tool_call_id`s intact, and in order. - [ ] Passing the export to `add_messages()` reproduces the same rows. - [ ] Sending the export to a chat-completions endpoint (mocked) is accepted. Every `tool_call_id` matches a call in an earlier assistant turn. - [ ] Tests in `tests/structs/test_conversation.py`. **File:** `swarms/structs/conversation.py`
Proposed by kyegomezPart of #2413 ## Problem `HierarchicalSwarm(director=Agent(...))`, as written in CLAUDE.md, fails on every run with `ValueError: Director output is not valid JSON`. The `OrderBatch` tool schema and the director prompt are only attached in `setup_director()`, which runs only when `director is None`. A director the caller builds has no schema, so it answers in prose and `parse_orders` rejects the answer. #2413 lists this row as arguably a code bug rather than a doc bug. ## Change In `reliability_checks`, when the caller passes an `Agent` director that has no tool schemas of its own, the swarm gives it the `OrderBatch` schema. It writes the schema onto the director's existing `LiteLLM` as well, because that instance reads its tool list on every request. Nothing is rebuilt, so the director's model settings stay as the caller configured them. The swarm already adjusts every agent it receives by forcing `output_type="final"`, so changing the caller's director has precedent. Two cases are left alone: - a director that already has tools, since the caller has set up its own contract; - a director with its own `llm=` object or with MCP configured; - a director that is not an `Agent`. ## Verification - New test `test_caller_director_agent_gets_the_order_schema` in `tests/structs/test_hierarchical_swarm.py`. It mocks `litellm` completion: the director answers in prose when it has no tools, and with an `OrderBatch` tool call when it has them. On master the run fails with `Director output is not valid JSON: 'Prose plan.'`. Here, the worker receives its order. - `test_caller_director_keeps_its_own_llm` checks that a director built with its own `llm=` is left alone. - `tests/structs/test_hierarchical_swarm.py` fails the same 5 tests on master and on this branch, plus the new test on master. The 5 are live `gpt-5.4` tests and there is no API key here. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcomPart of #2413 ## Problem `Node` is exported from `swarms`, and CLAUDE.md builds graphs with `wf.add_node(Node(id="analyst", type=NodeType.AGENT, agent=analyst))`. `add_node` wraps whatever it receives in `Node.from_agent`, so a `Node` gets wrapped in a second `Node`. That outer `Node` finds no `agent_name` or `name` on the inner one, and the call fails with `ValueError: Node id could not be auto-assigned. Please provide an id.` #2413 lists this row as arguably a code bug rather than a doc bug, because the public class can't be used with the method meant for it. ## Change `add_node` now adds a `Node` as given, keeping its own `id`, `type`, `agent` and `metadata`. The compile step for a nested workflow now runs on `node.agent`, so a prebuilt `SUBGRAPH` node gets compiled too. Passing an `Agent` or a `GraphWorkflow` works exactly as before. - `GraphWorkflow.from_spec` now hands each spec `Node` straight to `add_node`. Before, it passed only `node.agent`, which dropped the spec's own node ids, so edges that named those ids could not connect. - SKILL.md's pitfall table loses its `add_node(Node(...))` row, which this change makes untrue. That is the only rendered change: | before | after | |---|---| | 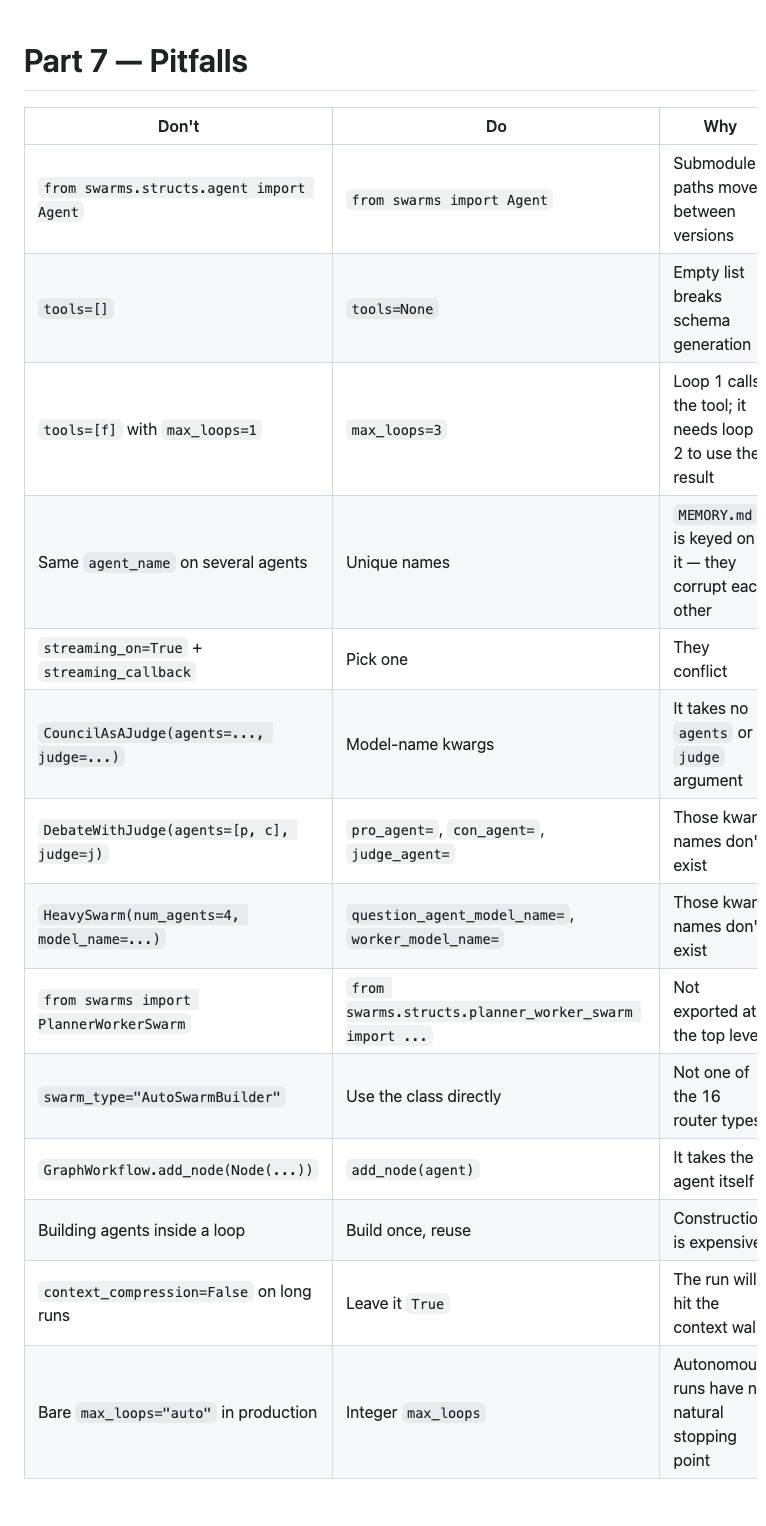 | 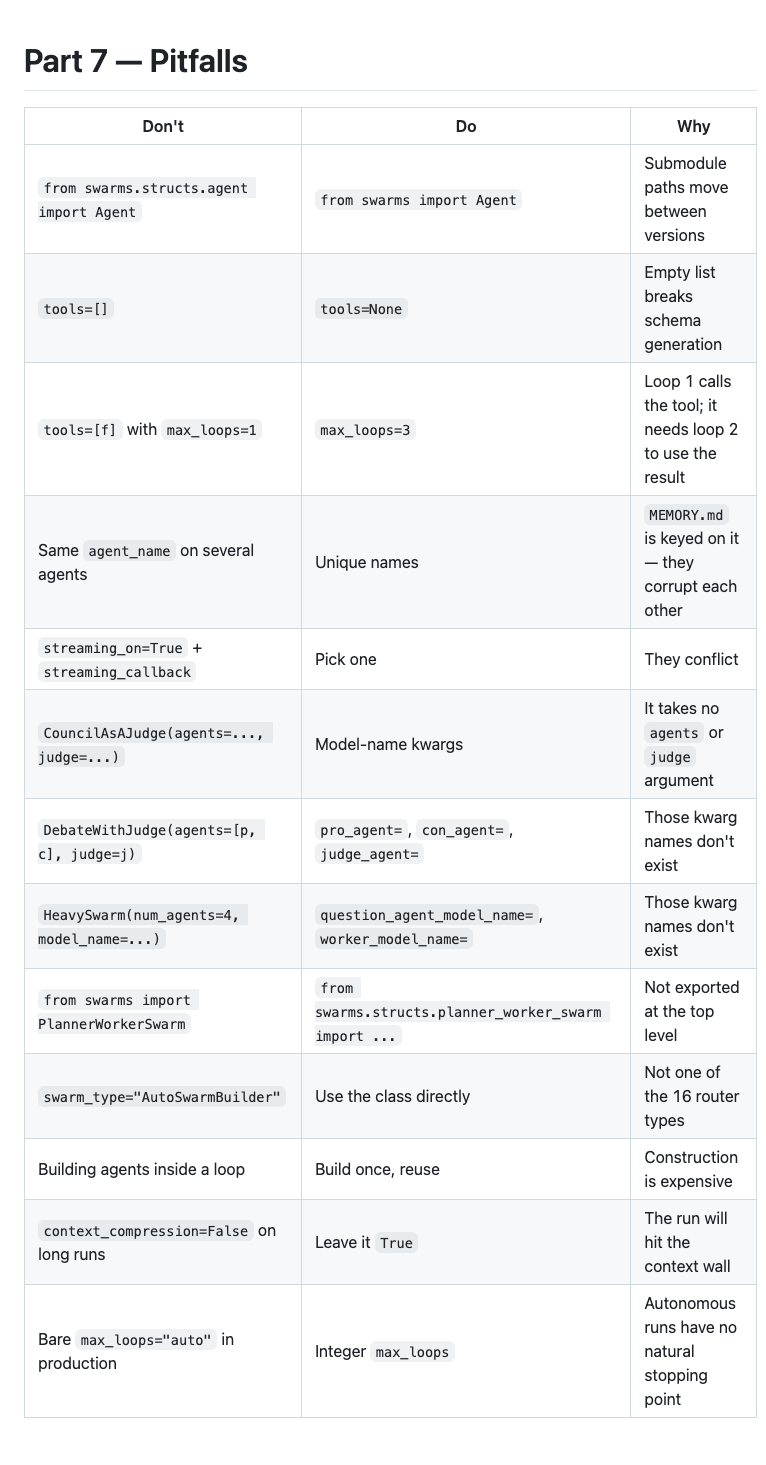 | ## Verification - New test `test_add_node_accepts_a_prebuilt_node` in `tests/structs/test_graph_workflow.py`. It adds two `Node`s with custom ids, connects them by id, runs the workflow, and reads the results by those ids. It fails on master with the error above and passes here. - New test `test_from_spec_keeps_node_ids` checks that a spec built with custom node ids keeps them, along with the edge between them. - `tests/structs/test_graph_workflow.py`: 74 passed, 11 skipped (the rustworkx-only tests). 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcomCloses #2392 `Agent.arun` was `asyncio.to_thread(self.run, ...)`, so every agent waiting on its provider held an OS thread, and `ConcurrentWorkflow` gave each agent its own thread from a pool capped at `MAX_CONCURRENT_AGENTS = 32`. At 100 agents with a 0.5s model call, master's `run` takes 2.07s, 24% of ideal, which matches the 23% in the issue. ## What changed - `Agent.arun` now awaits the model call through `LiteLLM.arun` (litellm's `acompletion`) instead of running all of `run()` in a thread. - `ConcurrentWorkflow.arun` is new. It gathers each agent's `arun` behind an `asyncio.Semaphore` sized by `_resolve_max_workers()`. The default cap still guards rate limits, and `max_workers=100` now means 100 concurrent model calls without 100 threads. - `run()` is unchanged for sync callers. ## How The bodies of `run()` and `_run` became generators (`_run_flow`, `_run_steps`). Each blocking call is yielded as a `functools.partial`: the model call, tool calls, planning, prompt auto-generation, context compression, the loop interval and fallback models. `run()` drives them inline, so it makes the same calls in the same order. `arun()` drives them on the event loop: the model call is awaited through the new `Agent.acall_llm` / `LLMManager.acall`, and everything else runs in a worker thread. There's one loop body and two drivers, so the sync and async paths can't drift apart. ## What is awaited and what still uses a thread Awaited on the event loop: the model call for `max_loops=1`, integer loops, `n > 1`, and agents with tools. For tools, the model turn is awaited and the tool call runs in a thread. Still in a worker thread: - tool execution, `plan`, prompt auto-generation and context compression - `max_loops="auto"`, which runs the whole autonomous loop in one thread - fallback models - streaming (`stream` or `streaming_on`) - an llm without a coroutine `arun` - a `call_llm` or `_run` overridden on a subclass or instance `arun` runs the whole `run()` in a thread, as before, for an interactive agent, a call with extra positional args, or an agent whose `run` is overridden. That keeps subclass and instance overrides of `run` working. `ConcurrentWorkflow` records results through one `_record` helper shared by `run` and `arun`, so failures and `on_error` behave the same way. With `show_dashboard`, `arun` falls back to `run` in a thread so the dashboard still shows. ## Benchmark Offline, with `completion` and `acompletion` stubbed at a fixed 0.5s, one fresh process per row: | agents | master `run` (cap 32) | `run(max_workers=n)` | `arun(max_workers=n)` | |---|---|---|---| | 10 | 0.51s, 98%, 15 threads | 0.51s, 99%, 15 threads | 0.50s, 99%, 10 threads | | 50 | 1.02s, 49%, 37 threads | 0.51s, 97%, 55 threads | 0.51s, 98%, 19 threads | | 100 | 2.07s, 24%, 37 threads | 0.52s, 97%, 105 threads | 0.51s, 97%, 19 threads | RSS growth during the 100-agent run: +2.1 MB on master (capped), +5.1 MB with 100 threads, +1.6 MB with `arun`. The thread count for `arun` stays flat from 50 to 100 agents. ## Tests - `test_agent.py`: `arun` awaits `llm.arun` on the caller's own thread and never reaches `llm.run`. - `test_concurrent_workflow.py`: with `max_workers=2`, at most 2 agents are in flight and answers come back in agent order. The test holds agents with an `asyncio.Event` and yields once after it is set, so it fails if the semaphore is removed. Both fail with the source reverted to master and pass here. ## Verification - `test_concurrent_workflow.py`, `test_agent.py`, `test_autonomous_loop.py` and `test_llm_manager.py` fail the same 30 live-model tests as master. `test_agent_concurrent_execution` is one of them. - No new failures across `tests/structs` and `tests/agents`. - An offline stub gives identical output for a tool-calling turn under `run` and `arun`. - black and ruff are clean, and there are no new dependencies or added comments. ## Not in this PR - Telemetry: native `arun` skips `run()`, so it doesn't emit the `Agent.run` span, and the new `ConcurrentWorkflow.arun` has no span of its own. `trace_run` only wraps sync methods. Making it coroutine-aware would cover both, and I'd rather do that as its own change. - `arun` keeps the default cap at `min(len(agents), 32)` for rate limits, so going past 32 still needs `max_workers` set explicitly. - If kyegomez's #2399 (Transcript into Conversation) merges first, this needs a rebase in `_run`, or the other way round. ## Not run A real provider at 100 agents. The numbers above use stubbed latency. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by Steve-DustyPart of #2041 (the concurrency half: `MajorityVoting.run_concurrently` shares Agent objects across threads). ## What is wrong `run_concurrently` can record one task's vote in another task's result. #2229 gave each task its own `MajorityVoting` clone, which fixed the shared `Conversation`. The clones still share the voter agents and the consensus agent, though. `Agent` can't be deep-copied (`TypeError: cannot pickle '_thread.lock' object`), so sharing them is unavoidable. Each answer is read back with `agent_answer(agent)`, which returns the last message in that agent's `short_memory`. When two tasks call the same agent at once, the second task's reply can land in `short_memory` between the first task's `agent.run(...)` returning and the first task reading its answer. The first task then records the second task's vote as its own. The consensus agent has the same race. Deterministic repro on master, with no network: one voter whose reply names its task, and the first call held open until the second has replied: ``` FAILED tests/structs/test_majority_voting.py::test_run_concurrently_keeps_each_tasks_votes E At index 0 diff: 'vote:task-2' != 'vote:task-1' ``` `task-1`'s result holds `task-2`'s vote. ## What this changes `swarms/structs/majority_voting.py` only. A new `_answer(agent, ...)` runs `agent.run` and reads `agent_answer` under one lock per agent, so a call and its read can't interleave with another task's call on the same agent. The locks live in a dict the clones share, because `copy.copy` shares `__dict__` values. Voters and the consensus agent both go through `_answer`. Trade-off: an agent now serves one task at a time. Different agents still run in parallel, inside a task and across tasks. Two tasks running at the same moment on one `Agent` was never safe anyway, since `short_memory`, the loop state and autosave are all per-instance. ## Verification New test `test_run_concurrently_keeps_each_tasks_votes` in `tests/structs/test_majority_voting.py`. It forces the interleave with a `threading.Event`, not a sleep. The 2s wait timeout only runs on the fixed path, where the second call is blocked until the first one finishes. ``` master source: 1 failed (vote:task-2 != vote:task-1) this branch: 4 passed (the new test + the three existing offline MajorityVoting tests) ``` black and ruff are clean, and no-mistakes review/test/document/lint passed. ## Not in this PR `AgentRearrange._clone_for_task` deep-copies agents and quietly falls back to the shared instance when that fails, which it always does for `Agent`. So its concurrent helpers share agents the same way. That's left for its own PR.
 Proposed by ShryukGrandhi
Related: #2041 (a structure's state is never reset per task). This is the same leak on a path that issue does not list: the judges' own memory. ## What is wrong `CouncilAsAJudge` builds its judge agents once in `__init__` and reuses them on every `run()`. `run()` clears the council's `conversation`, but each judge is an `Agent` whose `short_memory` keeps every earlier prompt and answer. The judge call in `_evaluate_dimension` passes only the new prompt, so the judge builds its request from that memory. On the second `run()`, every judge is sent the first task and its own first verdict, then the second task. Repro with the provider call mocked (no network). The council is run twice and each request's roles are recorded: ``` master, second run(): 6 of 7 requests contain the first task judge request roles: ['system', 'user', 'assistant', 'user'] (task 1 prompt, verdict 1, task 2 prompt) aggregator request: no leak ``` The aggregator does not leak because it already passes `messages=prior`, built from the council's own conversation. ## What this changes The judge call passes `messages=[]`, the same per-call path the aggregator uses. A judge then gets this run's prompt and nothing else: ``` this PR, second run(): 0 of 7 requests contain the first task judge request roles: ['system', 'user'] ``` `swarms/structs/council_as_judge.py`: 1 line. ## Verification New `tests/structs/test_council_as_judge.py`. No file owned `CouncilAsAJudge` tests, and the repo keeps one test file per module. It runs the council twice with a mocked `completion` and asserts that every second-run request contains the second task and none contains the first. ``` master source: FAILED assert not any("FIRST-TASK-ALPHA" in r for r in second_run) this PR: 1 passed ``` The `CouncilAsAJudge` cases in `tests/structs/test_component_ids.py` pass (8 passed). black and ruff are clean. ## Limitations Each judge's `short_memory` still grows across runs, because the agent records its own turns. It is no longer sent to the model. Running against a live model was not tested.
Proposed by ShryukGrandhi## What is wrong `grid_swarm` and `pyramid_swarm` take tasks off the caller's own list with `tasks.pop(0)`. When the call returns, the caller's `tasks` list is empty. `grid_swarm` also records that same list object as its opening `User` turn, so the history it returns shows the task list as `[]`. Repro on master, with two stub agents and no network: ```python tasks = ["t1", "t2", "t3", "t4"] out = grid_swarm(agents, tasks, output_type="dict") print(tasks) # [] print([m for m in out if m["role"] == "User"]) # [{'role': 'User', 'content': []}] tasks2 = ["p1", "p2", "p3"] pyramid_swarm(agents3, tasks2) print(tasks2) # [] ``` A caller who reuses the list, for example to run it again or to log what was asked, gets nothing back and no error. ## The fix Both functions pop from a copy, `task_queue = tasks.copy()`. `mesh_swarm` in the same file already does exactly this. Which agent gets which task does not change. `swarms/structs/swarming_architectures.py`: 2 lines added, 4 changed. ## Verification One test added to the existing `tests/structs/test_swarming_architectures.py`. It runs both helpers with recording stub agents. It checks that the caller's lists are unchanged, that `grid_swarm`'s first turn still holds all four tasks, and that the agents received the tasks in order. ``` master source: FAILED assert [] == ['t1', 't2', 't3', 't4'] this branch: 7 passed (the new test plus the 6 existing ones) ``` black and ruff are clean. ## Not changed `grid_swarm` still runs only the first `int(sqrt(len(agents)))**2` agents, and `pyramid_swarm` only as many as fill its last full level. Any tasks beyond that are still left unrun. That is how both functions are laid out, and changing it is a separate decision.
Proposed by ShryukGrandhiUpdates the requirements on [ruff](https://github.com/astral-sh/ruff) to permit the latest version. <details> <summary>Release notes</summary> <p><em>Sourced from <a href="https://github.com/astral-sh/ruff/releases">ruff's releases</a>.</em></p> <blockquote> <h2>0.16.10</h2> <h2>Release Notes</h2> <p>Released on 2026-10-01.</p> <h3>Preview features</h3> <ul> <li>Add a migration guide for categories (<a href="https://redirect.github.com/astral-sh/ruff/pull/28087">#28087</a>)</li> <li>[<code>pyupgrade</code>] Add rule for context manager iterator annotations (<code>UP052</code>) (<a href="https://redirect.github.com/astral-sh/ruff/pull/29000">#29000</a>)</li> </ul> <h3>Performance</h3> <ul> <li>Reduce memory used by diagnostics (<a href="https://redirect.github.com/astral-sh/ruff/pull/28951">#28951</a>)</li> </ul> <h3>Server</h3> <ul> <li>Avoid running <code>uv format</code> in untrusted workspaces (<a href="https://redirect.github.com/astral-sh/ruff/pull/28873">#28873</a>)</li> </ul> <h3>Documentation</h3> <ul> <li>Fix links to moved changelog sections and renamed mdtests (<a href="https://redirect.github.com/astral-sh/ruff/pull/28941">#28941</a>)</li> <li>Add Python 3.15 as a supported version (<a href="https://redirect.github.com/astral-sh/ruff/pull/28907">#28907</a>)</li> <li>Add ty as a type checker example (<a href="https://redirect.github.com/astral-sh/ruff/pull/28906">#28906</a>)</li> </ul> <h3>Other changes</h3> <ul> <li>Update Rust toolchain to 1.99 and MSRV to 1.97 (<a href="https://redirect.github.com/astral-sh/ruff/pull/29047">#29047</a>)</li> </ul> <h3>Contributors</h3> <ul> <li><a href="https://github.com/ntBre"><code>@ntBre</code></a></li> <li><a href="https://github.com/spaceone"><code>@spaceone</code></a></li> <li><a href="https://github.com/HardMax71"><code>@HardMax71</code></a></li> <li><a href="https://github.com/charliermarsh"><code>@charliermarsh</code></a></li> </ul> <h2>Install ruff 0.16.10</h2> <h3>Install prebuilt binaries via shell script</h3> <pre lang="sh"><code>curl --proto '=https' --tlsv1.2 -LsSf https://releases.astral.sh/github/ruff/releases/download/0.16.10/ruff-installer.sh | sh </code></pre> <h3>Install prebuilt binaries via powershell script</h3> <pre lang="sh"><code>powershell -ExecutionPolicy Bypass -c "irm https://releases.astral.sh/github/ruff/releases/download/0.16.10/ruff-installer.ps1 | iex" </code></pre> <h2>Download ruff 0.16.10</h2> <!-- raw HTML omitted --> </blockquote> <p>... (truncated)</p> </details> <details> <summary>Changelog</summary> <p><em>Sourced from <a href="https://github.com/astral-sh/ruff/blob/main/CHANGELOG.md">ruff's changelog</a>.</em></p> <blockquote> <h2>0.16.10</h2> <p>Released on 2026-10-01.</p> <h3>Preview features</h3> <ul> <li>Add a migration guide for categories (<a href="https://redirect.github.com/astral-sh/ruff/pull/28087">#28087</a>)</li> <li>[<code>pyupgrade</code>] Add rule for context manager iterator annotations (<code>UP052</code>) (<a href="https://redirect.github.com/astral-sh/ruff/pull/29000">#29000</a>)</li> </ul> <h3>Performance</h3> <ul> <li>Reduce memory used by diagnostics (<a href="https://redirect.github.com/astral-sh/ruff/pull/28951">#28951</a>)</li> </ul> <h3>Server</h3> <ul> <li>Avoid running <code>uv format</code> in untrusted workspaces (<a href="https://redirect.github.com/astral-sh/ruff/pull/28873">#28873</a>)</li> </ul> <h3>Documentation</h3> <ul> <li>Fix links to moved changelog sections and renamed mdtests (<a href="https://redirect.github.com/astral-sh/ruff/pull/28941">#28941</a>)</li> <li>Add Python 3.15 as a supported version (<a href="https://redirect.github.com/astral-sh/ruff/pull/28907">#28907</a>)</li> <li>Add ty as a type checker example (<a href="https://redirect.github.com/astral-sh/ruff/pull/28906">#28906</a>)</li> </ul> <h3>Other changes</h3> <ul> <li>Update Rust toolchain to 1.99 and MSRV to 1.97 (<a href="https://redirect.github.com/astral-sh/ruff/pull/29047">#29047</a>)</li> </ul> <h3>Contributors</h3> <ul> <li><a href="https://github.com/ntBre"><code>@ntBre</code></a></li> <li><a href="https://github.com/spaceone"><code>@spaceone</code></a></li> <li><a href="https://github.com/HardMax71"><code>@HardMax71</code></a></li> <li><a href="https://github.com/charliermarsh"><code>@charliermarsh</code></a></li> </ul> <h2>0.16.9</h2> <p>Released on 2026-09-24.</p> <h3>Preview features</h3> <ul> <li>[<code>ruff</code>] Avoid false positives for overloaded division (<code>RUF069</code>) (<a href="https://redirect.github.com/astral-sh/ruff/pull/28309">#28309</a>)</li> </ul> <h3>Bug fixes</h3> <ul> <li>[<code>flake8-bugbear</code>] Avoid false positives for calls with keyword arguments (<code>B009</code>, <code>B010</code>, <code>B043</code>) (<a href="https://redirect.github.com/astral-sh/ruff/pull/28776">#28776</a>)</li> <li>[<code>flake8-tidy-imports</code>] Allow lazy imports to be used in deferred annotations (<code>TID255</code>) (<a href="https://redirect.github.com/astral-sh/ruff/pull/28767">#28767</a>)</li> </ul> <h3>Rule changes</h3> <ul> <li>Update LibCST-based fixes for Python 3.15 (<a href="https://redirect.github.com/astral-sh/ruff/pull/28616">#28616</a>)</li> </ul> <!-- raw HTML omitted --> </blockquote> <p>... (truncated)</p> </details> <details> <summary>Commits</summary> <ul> <li><a href="https://github.com/astral-sh/ruff/commit/3265ed1f944c98bb4c04d632fbefb1257cdb583d"><code>3265ed1</code></a> Bump version to 0.16.10 (<a href="https://redirect.github.com/astral-sh/ruff/issues/29055">#29055</a>)</li> <li><a href="https://github.com/astral-sh/ruff/commit/e786964450e75d904c288a1e59ae2b196d0b9c47"><code>e786964</code></a> Authorize shared PR security-review workflow to publish findings (<a href="https://redirect.github.com/astral-sh/ruff/issues/29052">#29052</a>)</li> <li><a href="https://github.com/astral-sh/ruff/commit/a81291e9db2f67039d159e7490b988e6c25c7a0f"><code>a81291e</code></a> [ty] Defer uv workspace discovery until after project configuration (<a href="https://redirect.github.com/astral-sh/ruff/issues/28525">#28525</a>)</li> <li><a href="https://github.com/astral-sh/ruff/commit/b6a74d26cbe6b45b3eb2992041714461bd4ceb5b"><code>b6a74d2</code></a> [ty] Refresh uv project metadata when uv files change (<a href="https://redirect.github.com/astral-sh/ruff/issues/28529">#28529</a>)</li> <li><a href="https://github.com/astral-sh/ruff/commit/41d30df6fdbe215390b3acb46e8cd4017f65580d"><code>41d30df</code></a> Update Rust toolchain to 1.99 and MSRV to 1.97 (<a href="https://redirect.github.com/astral-sh/ruff/issues/29047">#29047</a>)</li> <li><a href="https://github.com/astral-sh/ruff/commit/317e0a3ab75878eba6e3b78c57f73d47108e2a8e"><code>317e0a3</code></a> [ty] Bound nested callable signature display (<a href="https://redirect.github.com/astral-sh/ruff/issues/29049">#29049</a>)</li> <li><a href="https://github.com/astral-sh/ruff/commit/8546752d9d5dac8da78c8abba380600cfe573874"><code>8546752</code></a> [ty] Fix member lookup on union-bounded type variables (<a href="https://redirect.github.com/astral-sh/ruff/issues/29018">#29018</a>)</li> <li><a href="https://github.com/astral-sh/ruff/commit/56180bcf800d6e45fb1c4b4113e97501b8f128c5"><code>56180bc</code></a> [ty] Specialize instance members once (<a href="https://redirect.github.com/astral-sh/ruff/issues/29043">#29043</a>)</li> <li><a href="https://github.com/astral-sh/ruff/commit/aa9a1ff88aa83b3f01360ef5b3cb04b2be187206"><code>aa9a1ff</code></a> [ty] Avoid stale I/O diagnostics when closing deleted files (<a href="https://redirect.github.com/astral-sh/ruff/issues/28988">#28988</a>)</li> <li><a href="https://github.com/astral-sh/ruff/commit/2d253467b5153f82d26c51d49eb8d4156f1768bf"><code>2d25346</code></a> [ty] Improve <code>unresolved-import</code> documentation (<a href="https://redirect.github.com/astral-sh/ruff/issues/29039">#29039</a>)</li> <li>Additional commits viewable in <a href="https://github.com/astral-sh/ruff/compare/0.5.1...0.16.10">compare view</a></li> </ul> </details> <br /> Dependabot will resolve any conflicts with this PR as long as you don't alter it yourself. You can also trigger a rebase manually by commenting `@dependabot rebase`. [//]: # (dependabot-automerge-start) [//]: # (dependabot-automerge-end) --- <details> <summary>Dependabot commands and options</summary> <br /> You can trigger Dependabot actions by commenting on this PR: - `@dependabot rebase` will rebase this PR - `@dependabot recreate` will recreate this PR, overwriting any edits that have been made to it - `@dependabot show <dependency name> ignore conditions` will show all of the ignore conditions of the specified dependency - `@dependabot ignore this major version` will close this PR and stop Dependabot creating any more for this major version (unless you reopen the PR or upgrade to it yourself) - `@dependabot ignore this minor version` will close this PR and stop Dependabot creating any more for this minor version (unless you reopen the PR or upgrade to it yourself) - `@dependabot ignore this dependency` will close this PR and stop Dependabot creating any more for this dependency (unless you reopen the PR or upgrade to it yourself) </details>
 Proposed by dependabot[bot]
Part of #2413 #2430 covers the Conversation and CouncilAsAJudge rows of #2413. This PR fixes the other examples and does not touch the sections #2430 changes. ## Problem These CLAUDE.md examples raise or misbehave on current master. I checked each one by running the snippet as written, with the LLM mocked: | Example | What happens on master | |---|---| | `wf.add_node(Node(id=..., type=NodeType.AGENT, agent=...))` | `ValueError: Node id could not be auto-assigned`. `add_node` takes an `Agent` or a `GraphWorkflow`. | | GraphWorkflow `streaming_callback=lambda tok: ...` | It is called as `(node_id, token)`, so every node fails with a swallowed TypeError. It also only fires when the agents have `streaming_on=True`. | | `HierarchicalSwarm(director=Agent(...))` | `ValueError: Director output is not valid JSON`. The OrderBatch schema is only attached to a director the swarm builds itself. | | `DebateWithJudge(agents=[pro, con], judge=judge)` | `TypeError: unexpected keyword argument 'judge'` | | `HeavySwarm(num_agents=4, ...)` | `TypeError: unexpected keyword argument 'num_agents'` | | `from swarms import PlannerWorkerSwarm` with `planner_agent=`, `worker_agents=` | `ImportError`. With a direct import, the two keywords are swallowed and it raises `requires at least one worker agent`. | | `run_agents_with_different_tasks({agent: task})` | `KeyError: slice(0, 10, None)`. It takes a list of `(agent, task)` pairs. | | `results.items()` after `ConcurrentWorkflow.run` | `AttributeError`. `run` returns a list of messages. | | SwarmRouter table row `"AutoSwarmBuilder"` | Not a valid `swarm_type`. | | `thinking_tokens` default `None`; `think` tool tied to `thinking_tokens` | The default is `1024`, and the `think` tool is controlled by `think_tool`. | | GroupChat `idle_timeout` | Never read. Its own docstring marks it unused. | ## Change Each example now uses the real API: agents passed to `add_node`, a two-argument stream callback with `streaming_on` agents, `director_model_name`, `agents=[pro, con, judge]`, HeavySwarm's real constructor arguments, the submodule import with `planner_model_name` and `agents=`, a list of pairs, and iterating over the returned messages. I deleted the stale table row and the `idle_timeout` mentions, and corrected the two defaults. Only CLAUDE.md changes: +28/-46. I left the GroupChat "no agent speaks" row unchanged, because master already forces `output_type="final"` when an agent decides whether to speak. I also left out the MCP `/sse` row, which the issue says is filed separately. ## Before / after GraphWorkflow: | before | after | |---|---| | 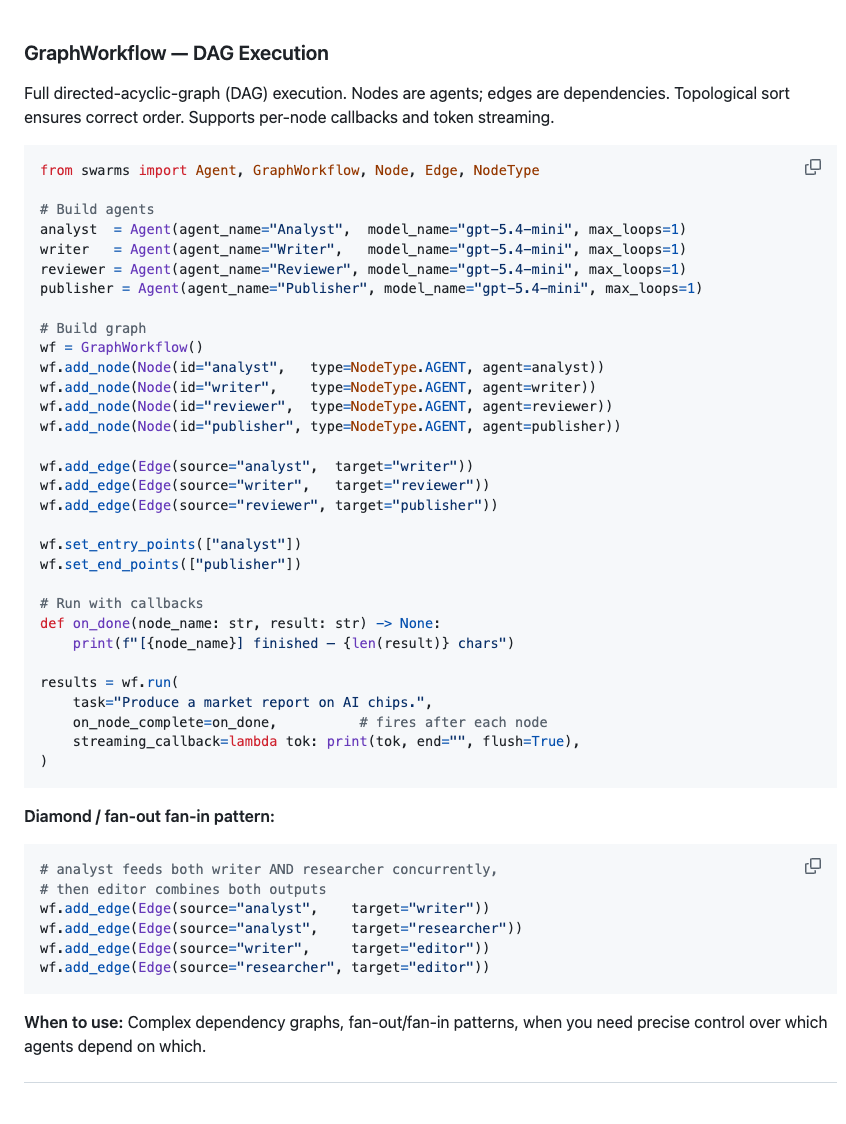 | 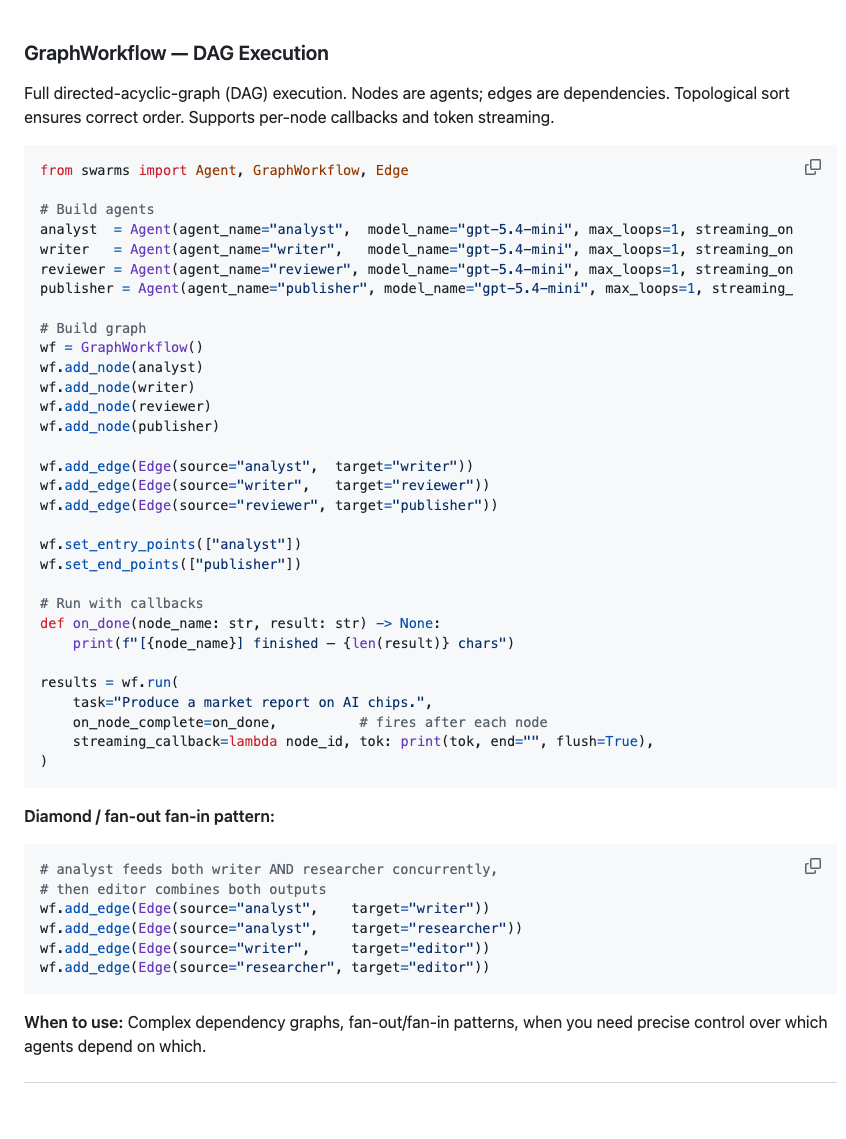 | DebateWithJudge and HeavySwarm: | before | after | |---|---| |  |  | ## Verification Each rewritten snippet runs to completion with `swarms.utils.litellm_wrapper.completion` mocked. The GraphWorkflow one delivers streamed tokens through the new callback, DebateWithJudge resolves the Pro, Con and Judge roles, and the HierarchicalSwarm director's orders reach the workers. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcomFixes #2410 Items 1 to 3 of #2410 landed in #2443 and #2444. This is item 4. ## Problem With `max_loops >= 2` and the default `reasoning_prompt_on=True`, `Agent._run` stores the "Current Internal Reasoning Loop" and "Final Internal Reasoning Loop" notes under the agent's own role, so they are sent as assistant turns. Every request therefore ends on an assistant turn: the loop note in the first call, and the model's previous reply after that. Current Claude models reject a request that ends on an assistant turn, because they read it as a prefill. The issue's repro on master: ``` call 1: ['system', 'user', 'assistant'] last: Current Internal Reasoning Loop: 1/3 call 2: ['system', 'user', 'assistant', 'assistant'] last: answer 1 call 3: ['system', 'user', 'assistant', 'assistant', 'assistant'] last: answer 2 ``` ## Change The loop notes are now user turns. Loop 1's notes go into `short_memory` before the transcript is built, as before. Later loops also append them to the live transcript through the existing `_memory_and_transcript`, because the transcript is only built once. With this change: ``` call 1: ['system', 'user', 'user'] last: Current Internal Reasoning Loop: 1/3 call 2: ['system', 'user', 'user', 'assistant', 'user'] last: Current Internal Reasoning Loop: 2/3 call 3: [..., 'assistant', 'user', 'user'] last: Final Internal Reasoning Loop: 3/3 ... ``` Every request now ends on a user turn, and the model still sees its own earlier replies. I sent the notes as user turns rather than dropping them, because without a user turn after loop 1 the next request still ends on the model's previous reply. ## Verification - New test `test_every_loop_request_ends_on_a_user_turn` in `tests/structs/test_agent.py` mocks `litellm` completion and asserts that all three requests of a `max_loops=3` run end on a user turn. It fails on master and passes here. - `tests/structs/test_agent.py`, `tests/structs/test_conversation.py` and `tests/agents` give 32 failed / 536 passed. Master fails the same 32 tests, which make live LLM calls, plus the new one. - The request shapes were checked with `litellm` completion mocked. I did not send a request to the live Anthropic API, because there is no key here. ## Not done - With `reasoning_prompt_on=False`, loops after the first still end on the model's previous reply, because nothing is added between loops. That needs a decision on what to send instead, so it is left for a follow-up. - This touches the same lines as #2399, which marks these notes `internal=True` so they are not sent at all. Whichever lands second needs a small merge. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcomFixes #2459 ## Problem `_remove_a_key` deletes `title` from any dict that also has a `type` key, which is how it strips Pydantic's schema-level titles. It also walks into the `properties` map, whose keys are the model's field names. A model with a field named `type` makes that map look like a schema node, so a field named `title` is deleted from `properties` while it stays in `required`. The tool schema then asks the model for a field it never describes. This reaches `base_model_to_openai_function`, `BaseTool.base_model_to_dict` (and so `Agent(tool_schema=...)`), and nested models under `$defs`. ## Change When the key is `properties`, the function now recurses into each property's schema instead of treating the field-name map as a schema node. Schema-level `title` and `additionalProperties` are still removed. This is 3 lines. ## Verification - New test in `tests/tools/test_output_str_fix.py`, the file that already tests `base_model_to_openai_function`. It covers a flat `Ticket(title, type, body)` and the same model nested under `$defs`. On master `properties` is `['type', 'body']`; here it is `['title', 'type', 'body']`. The test also checks that each field's own `title` and the schema-level `title` are still removed. - `tests/tools/test_output_str_fix.py`: 6 passed. `tests/tools/test_base_tool.py` fails the same 3 tests on master and on this branch. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcomFixes #2458 ## Problem `GKPAgent` builds its knowledge generator, reasoner and coordinator once and reuses them for every call. With the default `output_type="str-all-except-first"`, each `agent.run` returns that agent's whole transcript so far. The parsers take the first `Knowledge 1:`, `Explanation:` or `Final Answer:` they find, which belongs to an earlier call. Within one query, reasoning paths 2..N report path 1's explanation. A second query returns the first query's final answer. `ReasoningAgentRouter(swarm_type="GKPAgent")` goes through the same code. ## Change The three agents are built with `output_type="final"`, so `run` returns only the latest reply, which is what the parsers already assume. This is 3 lines. Each reasoning path still sees the earlier paths in its own memory, because the reasoner is shared. Giving every path a fresh agent would make the paths fully independent, but it would also change how the agents' usage is tracked, so I left that out of this fix. ## Verification - New `tests/agents/test_gkp_agent.py`. No test file existed for this module. It mocks `Agent.call_llm`, then asserts that a query's two paths come back as `path 1.` / `path 2.` with clean answers, and that a second query returns its own answer. It fails on master and passes here. - `tests/structs/test_reasoning_agent_router.py` fails the same 5 tests on master and on this branch. They make live LLM calls and there is no API key. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcom## Summary `_remove_a_key` (`swarms/tools/pydantic_to_json.py:7-23`) strips `title` from every dict that also has a `type` key, so it removes the schema-level titles Pydantic adds. But it also runs on the `properties` map itself, whose keys are the model's field names. If a model has a field called `type`, that map looks like a schema node, and a field called `title` gets deleted from `properties` while it is still listed in `required`. The model is then asked for a field the schema never describes. It reaches `base_model_to_openai_function`, `BaseTool.base_model_to_dict` (so `Agent(tool_schema=...)`) and nested models under `$defs`. Ticket- and issue-shaped models have exactly these two fields. ## Reproduction ```python from pydantic import BaseModel from swarms.tools.pydantic_to_json import base_model_to_openai_function class Ticket(BaseModel): title: str type: str body: str params = base_model_to_openai_function(Ticket)["functions"][0]["parameters"] print(list(params["properties"]), params["required"]) ``` On master (`4278ec4b`): `['type', 'body'] ['title', 'type', 'body']`. Expected: `['title', 'type', 'body'] ['title', 'type', 'body']`. ## Fix When the key is `properties`, recurse into each property's schema instead of treating the field-name map as a schema node.
Proposed by sakshamchitkara-dotcom## Summary `GKPAgent` builds its knowledge generator, reasoner and coordinator once (`swarms/agents/gkp_agent.py:46`, `:201`, `:363`) and reuses them for every call. They keep the default `output_type="str-all-except-first"`, so each `agent.run` returns that agent's whole growing transcript rather than its latest reply. The parsers then take the first `Knowledge 1:`, `Explanation:` or `Final Answer:` they find in that text, which belongs to an earlier call. The result: - Within one query, every reasoning path after the first reports path 1's explanation, and its answer carries the rest of the transcript. - A second query returns the previous query's final answer. `ReasoningAgentRouter(swarm_type="GKPAgent")` goes through the same code. ## Reproduction The LLM is mocked per agent; no network calls. ```python from swarms.structs.agent import Agent from swarms.agents.gkp_agent import GKPAgent paths = {"n": 0} def fake_llm(self, task=None, *args, **kwargs): prompt = [m for m in self.short_memory.conversation_history if m["role"] == "Human"][-1]["content"] city = "Canberra" if "Australia" in prompt else "Paris" if self.agent_name.endswith("knowledge-generator"): return f"Knowledge 1: {city} fact one.\n\nKnowledge 2: {city} fact two." if self.agent_name.endswith("coordinator"): return f"Analysis: paths agree.\nFinal Answer: {city}" paths["n"] += 1 return f"Explanation: path {paths['n']}.\nConfidence: high\nAnswer: {city}" Agent.call_llm = fake_llm gkp = GKPAgent(agent_name="gkp", model_name="gpt-4o-mini", num_knowledge_items=2) detail = gkp.process("What is the capital of Australia?") print([(r["explanation"], r["answer"][:45]) for r in detail["reasoning_results"]]) print(repr(gkp.run("What is the capital of France?"))) ``` On master (`4278ec4b`): ``` [('path 1.', 'Canberra'), ('path 1.', 'Canberra\nQuestion: What is the capital of Aus')] 'Canberra\nQuestion: What is the capital of France?\n\nReasoning Path 1:\nKnowledge: Canberra fact one.' ``` Expected: `[('path 1.', 'Canberra'), ('path 2.', 'Canberra')]`, then `'Paris'`. ## Fix Set `output_type="final"` on the three agents, so `run` returns only the latest reply, as the parsers assume.
Proposed by sakshamchitkara-dotcom## What is wrong In a parallel step (`"A, B -> C"`), `AgentRearrange._run_concurrent_workflow` catches a failing agent's exception and stores it as that agent's result: ```python try: results[index] = future.result() except Exception as error: results[index] = error ``` The exception object is then written into the shared conversation as B's message. C receives the error text as if it were B's answer, and `run()` returns normally. The same failure in a sequential step (`"A -> B -> C"`) raises, and `test_agent_error_raises` already states the rule: "run() must raise when an agent's run() raises unexpectedly". It only checked a sequential flow. Repro on master, with B's provider failing: ``` sequential: raised AgentLLMError Agent 'B' got no response from 'gpt-4o-mini' after 1 attempt(s): rate limited concurrent: returned [..., {'role': 'B', 'content': AgentLLMError("Agent 'B' got no response ...")}, {'role': 'C', 'content': 'C ok'}] C was given: [..., "B: Agent 'B' got no response from 'gpt-4o-mini' after 1 attempt(s): rate limited"] ``` With `output_type="json"` the same run fails with `TypeError: Object of type AgentLLMError is not JSON serializable` (and `yaml` with a `RepresenterError`), which hides the real error behind a serialisation one. ## What this changes `future.result()` is no longer wrapped, so a failing agent's exception propagates. The executor's `with` block waits for the other agents in the step, then `run()` re-raises through its existing error path, exactly as a sequential step does. The `isinstance(result, Exception)` guard that only existed for the swallowed case is gone, so every result goes through `agent_answer`. `swarms/structs/agent_rearrange.py`: 2 lines replace 9. ## Verification New test `test_agent_error_in_a_parallel_step_raises` in `tests/structs/test_agent_rearrange.py`, next to `test_agent_error_raises`. The flow is `"ResearchAgent, WriterAgent -> ReviewerAgent"`, with WriterAgent raising and every agent's `run` stubbed (no network). It asserts that `run()` raises and that ReviewerAgent never runs. ``` master source: Failed: DID NOT RAISE TypeError this PR: 1 passed ``` black and ruff are clean. The other 16 failures in that file are live-LLM tests that fail the same way on master.
Proposed by ShryukGrandhi## What is wrong `SequentialWorkflow.run_concurrent(tasks)` returns its results in the order the tasks **finish**, not the order they were given: ```python return [ result.result() for result in as_completed(results) ] ``` So `results[i]` is usually not the answer to `tasks[i]`, and nothing fails or warns. The sibling `AgentRearrange.batch_run` and `concurrent_run` both return results in input order. Repro on master (one agent, `output_type="final"`, tasks finishing in reverse order): ``` 'task-0' -> 'A answered task-2' 'task-1' -> 'A answered task-1' 'task-2' -> 'A answered task-0' ``` ## What this changes Read the futures in the order they were submitted, and drop the `as_completed` import, which nothing else used. An exception still propagates from `result()` as before. `swarms/structs/sequential_workflow.py`: 1 line replaces 5. ## Verification New test `test_run_concurrent_returns_results_in_task_order` in `tests/structs/test_sequential_workflow.py`. It uses a real `Agent` with `call_llm` stubbed and no network. A `threading.Event` makes `task-0` finish last (no sleeps), the test asserts that ordering actually happened, and then it checks `results[i]` against `tasks[i]`. ``` master source: At index 0 diff: 'answer to task-1' != 'answer to task-0' this PR: 1 passed ``` black and ruff are clean. The other 6 failures in that file are live-LLM tests that fail the same way on master. The test needs at least 2 pool workers, since `run_concurrent` sizes its pool with `os.cpu_count()`. On a single-core host, `task-0` would run first and the event would time out. Standard CI runners have 2 or more cores.
Proposed by ShryukGrandhiCloses #2447 ## What is missing `MixtureOfAgents` only has `run()`. Async code (a FastAPI handler, an async queue worker) that calls it blocks the event loop for every worker layer and then for the aggregator, so callers wrap it in `asyncio.to_thread` themselves. ## What this adds - **`astep(task, img=None)`** awaits each worker's `agent.arun(task=task, img=img)` with `asyncio.gather`, with at most `max_workers` in flight through an `asyncio.Semaphore`. When `max_workers` is unset it uses `max_workers_95_percent()`, the same default `run_agents_concurrently` uses for `step()`. A worker that raises contributes its exception as its output, exactly as `step()` does, so the two paths record the same thing. - **`arun(task, img=None)`** runs the layers in order (each needs the previous layer's answers), then awaits `aggregator_agent.arun(task=..., messages=prior)`. Mixture-level errors return `"Error: ..."`, like `run()`. - **Shared bookkeeping.** `_run` and `arun` now share `_record_layer` (writes a layer's answers to the conversation and builds the next layer's input), `_aggregator_turn` and `_finish`, rather than copying that code. `run()` behaves exactly as before. ```python result = await moa.arun("Compare the three proposals.") ``` ## Verification Two tests in `tests/structs/test_moa.py`, no network, covering the acceptance list: - `test_arun_returns_what_run_returns`: `arun` output equals `run` output (`output_type="all"`) for `layers=1`, `layers=2`, a worker that raises, and an aggregator that raises (`"Error: Aggregator failed"` from both). - `test_arun_caps_workers_and_leaves_the_event_loop_free`: four workers with `max_workers=2`. Each worker blocks until a coroutine on the same loop has ticked, so a blocked loop would time them out; they pair at a `threading.Barrier(2)`, and peak concurrency is exactly 2. ``` master source: 2 failed (AttributeError: 'MixtureOfAgents' object has no attribute 'arun') this PR: 13 passed (whole test_moa.py) semaphore cap removed: assert 4 == 2 ``` black and ruff are clean. The no-mistakes gate also drove real `Agent`s over LiteLLM HTTP against a local OpenAI-compatible server: parity held in all four cases, the loop stayed responsive (worst gap 14ms during a 1.1s `arun`), and peak concurrency stayed at the cap. ## Limitations - As the issue notes, `Agent.arun` is still `asyncio.to_thread(self.run)`, so workers run on asyncio's default executor (`min(32, os.cpu_count() + 4)` threads). A `max_workers` above that is honoured by `run()` but capped lower by the executor in `arun`. Output is the same; only throughput differs. Moving `Agent.arun` onto `litellm.acompletion` removes this, and `arun` picks it up unchanged. - `arun` carries no `trace_run` span: the decorator wraps sync functions only, and the other `arun`s in the codebase are untraced for the same reason.
Proposed by ShryukGrandhiCloses #2417 `DecisionModel.build_payload()` validates `state` and `questions`, then spreads `self.extra_body` after the three request fields. So an `extra_body` entry named `model`, `state` or `questions` silently replaces the value that was just validated. On master: ```python client = DecisionModel( api_key="test", extra_body={"model": "other-model", "state": "replacement", "questions": {}}, ) client.build_payload("original", questions) # model: other-model | state: replacement | questions: {} ``` The request then asks a different model about different content, while `parse_response()` still checks the answers against the original `questions`. ## Fix `build_payload()` now raises `ValueError` before anything is sent when `extra_body` shares a key with `model`, `state` or `questions`. Other keys, like `beam_width`, still merge in as before. - **Rejected, not ignored.** Reordering the spread so the request fields win would also stop the override, but the caller would never learn their setting was dropped. The issue asks for a rejection as well. - **In `build_payload()`, not `__init__`.** The class documents overriding `build_payload()` for a provider with a different wire format. The three names are only reserved in this default format, so the check lives with it. ## Tests One parametrized test in `tests/structs/test_decision_model.py`, next to the existing `extra_body` test. For each of the three keys, `run()` raises and no request reaches the fake API. - With `decision_model.py` reverted to master, all 3 cases fail. With the fix, they pass. - The whole file passes: 111 tests. - `black` and `ruff` are clean on both files, and the diff adds no comments. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by Steve-DustyCloses #2448 ## What is wrong today `_serialize_attr` swaps any attribute `json.dumps` rejects for the string `"<Non-serializable: TypeName>"` and logs nothing, and there is no way to ask for a faithful dump. On master (`a87cece8`), a plain `Agent(agent_name="repro", model_name="gpt-4o-mini")` with no run, plus a two-attribute `SerializableMixin` subclass holding a `threading.Lock`, with a loguru sink counting warnings: ``` Agent placeholders: {'skills': '<Non-serializable: SkillsManager>', '_context_compressor': '<Non-serializable: ContextCompressor>', 'marketplace': '<Non-serializable: AgentMarketplaceHandler>', 'llm_manager': '<Non-serializable: LLMManager>', 'tool_manager': '<Non-serializable: ToolManager>', 'autonomous_loop': '<Non-serializable: AutonomousAgentLoop>', 'tool_struct': '<Non-serializable: BaseTool>'} Swarm.to_dict(): {'name': 's', 'lock': '<Non-serializable: lock>'} to_dict(strict=True) TypeError: SerializableMixin.to_dict() got an unexpected keyword argument 'strict' warnings logged: 0 [] ``` Every default Agent carries seven placeholder strings into `log_agent_data(self.to_dict())`, the `Agent State:` error text, and `to_json`/`to_yaml`/`to_toml`. `Agent` also had its own copy of `_serialize_callable`/`_serialize_attr`/`to_dict`, so a mixin-only fix would have missed it. ## What changed - `swarms/structs/serialization.py` (+31 / -8) - A module-level set records each `module.QualName.attr` and value type that has fallen back to the placeholder. The first time, it logs `module.QualName.attr (TypeName) is not serializable, replaced with a placeholder`. After that it stays quiet. The check and the add run under a lock, so concurrent `to_dict()` calls cannot both log. - `to_dict(strict: bool = False)` passes `strict` to `_serialize_attr`. With `strict=True` it raises `TypeError("module.QualName.attr (TypeName) is not serializable")`, chained from the `json` error. - A nested `SerializableMixin` value gets `strict` too, so `Outer().to_dict(strict=True)` raises `__main__.Outer.inner (Inner) is not serializable`, chained from the inner attribute's error, instead of returning the inner placeholder. Other nested `to_dict()` methods are still called without `strict`: none of them accepts it (`Conversation`, `MCPManager`, `tree_of_thoughts`, `planner_generator_evaluator` take no arguments, `GraphWorkflow` has its own), and the placeholder string is produced only in this file, so `strict` covers every placeholder this mixin can emit. - `to_dict` iterates `self.__dict__.copy()`. The deleted `Agent.to_dict` took that snapshot. The no-mistakes review caught that looping over the live dict let `run_concurrent_tasks` threads hit `dictionary changed size during iteration`. Its test step reproduced the race before this line and never after it. - `swarms/structs/agent.py` (+14 / -64) - `class Agent(SerializableMixin)`. The duplicate `_serialize_callable`, `_serialize_attr` and `to_dict` are deleted. - The exclusion list reuses the existing `_to_dict_exclude`: `llm`, the seven runtime helpers above, and `_workspace`. These are now left out quietly instead of showing up as placeholders. No reader needs them: nothing under `swarms/` indexes any of the eight keys, `log_agent_data` reads only `agent_name`, `name` and `id` and `json.dumps` the rest, the `Agent State:` text and `to_json`/`to_yaml`/`to_toml`/`save_to_yaml` dump the dict whole, and `save()`/`load()` go through `SafeStateManager` (`safe_loading.py`), which never calls `to_dict()`. - `tests/structs/test_agent.py` (+26): one test, described below. After, the same script: ``` Agent placeholders: {} Swarm.to_dict(): {'name': 's', 'lock': '<Non-serializable: lock>'} to_dict(strict=True) TypeError: __main__.Swarm.lock (lock) is not serializable warnings logged: 1 ['__main__.Swarm.lock (lock) is not serializable, replaced with a placeholder'] ``` ## Acceptance - [x] One warning naming class and attribute, even across repeated calls. Three `to_dict()` calls produce exactly one `swarms.structs.agent.Agent.placeholder_lock (lock) is not serializable, replaced with a placeholder`. An `Agent(tools=[fn], handoffs=[...])` logs `swarms.structs.agent.Agent.tools (list)` and `swarms.structs.agent.Agent.handoffs (list)` once each. - [x] `to_dict(strict=True)` raises on that same object: `TypeError: swarms.structs.agent.Agent.placeholder_lock (lock) is not serializable`. - [x] Exclusion list is silent. A default Agent logs nothing and has no placeholders. An Agent after `agent.workspace` (a `WorkspaceManager` in `_workspace`) logs nothing over two `to_dict()` calls. - [x] Test in `tests/structs/`: `TestToDictPlaceholder` in `tests/structs/test_agent.py`. ## Decision (2026-10-04) - `save_to_yaml` stays non-strict. An Agent built with `tools=[fn]` or `handoffs=[...]` stores them as lists `json.dumps` rejects. Measured: both become placeholders. A strict `save_to_yaml` would therefore raise for the most common Agent configuration, and nothing in the repo calls it. The warn-once log removes the silence there. Switching it later is one argument. - `_workspace` is excluded (owner decision). `save()`, and so every `autosave=True` run, turns it from `None` into a `WorkspaceManager`. Without the exclusion, autosave users would get a warning they cannot act on. - Warnings are keyed per `module.QualName.attr` and value type per process, so two same-named classes in different modules each get their own warning, and a later value of a different type on the same attribute warns again instead of staying silent. `Agent.to_dict()` runs on every `run()`, so a per-call warning would flood the logs. Overlap: my open #2263 makes the same `Agent(SerializableMixin)` change in `agent.py` as part of a wider cleanup, so whichever of the two lands second will conflict there. ## Verification - The test fails on master. With `git checkout upstream/master -- swarms/structs/serialization.py swarms/structs/agent.py`: ``` E AttributeError: module 'swarms.structs.serialization' has no attribute '_warned' 1 failed, 112 deselected in 1.39s ``` Restored: `1 passed`. The test clears the warn-once set first, so it does not depend on test order. It builds `Agent.__new__(Agent)` with no LLM, patches the module logger with a mock to count warnings, and checks strict with `pytest.raises(TypeError, match="Agent.placeholder_lock")`. - Same pass/fail on master and branch, with identical failing-test lists. The failures need provider API keys. - `test_agent.py`, `test_agent_rearrange.py` and `tests/telemetry/test_telemetry.py`: 50 failed on both; 305 passed on master, 306 on the branch (the new test). - The other mixin users' suites (`test_agent_registry`, `test_graph_workflow`, `test_groupchat`, `test_heavy_swarm`, `test_round_robin_swarm`, `test_self_moa_seq`, `test_swarm_router`): 27 failed / 290 passed on both. - `black . --check` (24.2.0, line length 70): `1017 files would be left unchanged.` `ruff check .` (0.2.1): clean. - no-mistakes (`--skip=rebase,pr,ci`): outcome `passed`. Review fixed the `__dict__` snapshot, and test added `_workspace` to the exclusion list. Its test step drove a real Agent against a local fake OpenAI server, with `autosave=True` and a forced error path, and also checked `AgentRearrange.to_dict()` and the thread race. ## Not done - Other structs' exclusion lists are outside this issue's two files. They now warn once for their own placeholders: `AgentRearrange.agents (list)`, `RoundRobinSwarm.agents (list)`, and on `SwarmRouter`, `agents (list)`, `_swarm_factory (dict)` and `workspace (WorkspaceManager)`.
Proposed by ayaangazaliFixes #2449 ## Problem `HierarchicalSwarm` only has `run()`. Async code that calls it blocks the event loop for the whole director, workers and feedback cycle, `max_loops` times over. The usual workaround is `await asyncio.to_thread(swarm.run, task)`, but that runs the whole swarm as one opaque call. Cancelling it or putting a timeout on it only stops the `await`. The swarm keeps running in the thread and calls every remaining agent. I measured this with a director that issues two sequential orders. I cancelled each version while the first worker was running: | | worker A calls | worker B calls | |---|---|---| | `asyncio.to_thread(swarm.run, ...)`, cancelled | 1 | 1 | | `swarm.arun(...)` from this PR, cancelled | 1 | 0 | ## Change This follows the issue's proposal. - `arun` follows the same loop as `run`. It uses async versions of every method that calls an agent: `astep`, `arun_director`, `aexecute_orders`, `_aexecute_orders_once`, `_aexecute_order_with_retries`, `acall_single_agent`, `_arequest_reassignment`, `afeedback_director` and `arun_judge_agent`. - Each agent call awaits the agent's own `arun` when it is a coroutine function, and otherwise runs `agent.run` through `asyncio.to_thread`. `Agent.arun` is still `to_thread(self.run)` today, so this PR still uses threads. It will use `litellm.acompletion` without any change here once `Agent.arun` does. - Parallel orders run through `asyncio.gather` behind `asyncio.Semaphore(self.max_workers)`. Their outputs are added to the conversation in order once all of them finish, so the history matches the sync path. - With `interactive=True`, the task is read through `asyncio.to_thread`. - The parts that don't wait on a model are now helpers that `run` and `arun` both call: the director prompt, the loop task, the loop markers, parallel result ordering, the recovery prompt, the recovery notes and the failure records. The text of every System marker and recovery note now comes from one place, so the two paths can't word them differently. - `run()` behaves as before, and there is no new constructor flag. `arun` is not wrapped in `@trace_run`, because that decorator only handles sync functions. ## Acceptance - [x] With a mocked director and workers, `arun` returns the same output and conversation history as `run`, with `parallel_execution` both `True` and `False`. - [x] A worker that fails `max_agent_retries + 1` times triggers reassignment under `arun` exactly as under `run`. The same parity test covers this: call counts are `[2, 2, 2]` for director, failing worker and healthy worker on both paths, and `[RECOVERY STARTED]` is in the history. - [x] A coroutine on the same loop keeps running while `arun` is in flight. The test's director blocks on a `threading.Event` that only a ticker coroutine can set, so a blocked loop fails the test instead of passing it. - [x] No more than `max_workers` orders run at once. The test's workers have an async `arun` that yields once while counting how many orders are in flight. The test asserts a peak of 2 for `max_workers=2` with 4 orders, and it fails when the semaphore is removed. - [x] Tests are in `tests/structs/test_hierarchical_swarm.py`. ## Verification - Both new tests fail on `master`. - I also broke the change on purpose four ways, and a test failed each time: dropping the semaphore, calling `agent.run` directly on the loop, ignoring an agent's async `arun`, and skipping the ordered history writes in the async parallel path. - `tests/structs/test_hierarchical_swarm.py` gives 32 passed and 5 failed. The same 5 fail on `master` because they make live `gpt-5.4` calls with no API key. - `black --check` (24.2.0, as pinned in CI) and `ruff check` are clean. ## Not done - When a worker fails, `Agent.arun` calls `_handle_run_error` again after `Agent.run` already did. So under `arun`, each failed attempt logs the agent error block twice, and with `autosave=True` it saves twice. Swarm behaviour (retries, reassignment, history) is unaffected. That is a separate fix in `Agent.arun`. - `MixtureOfAgents.arun` is tracked separately in #2447. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcom## Summary `HierarchicalSwarm` has no async entry point. If async code calls `run()` directly, the event loop is blocked for the whole director → workers → feedback cycle, repeated `max_loops` times. To avoid that, callers have to wrap `run()` in `asyncio.to_thread` themselves. This issue was split out of #2447, which now tracks `MixtureOfAgents.arun` on its own. ## Current behaviour - `run()` ([hiearchical_swarm.py#L564](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/hiearchical_swarm.py#L564)) calls `step()` `max_loops` times. - `step()` ([#L510](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/hiearchical_swarm.py#L510)) runs the director, parses its orders, executes them, then hands the outputs to either the judge (`run_judge_agent`) or the director for feedback (`feedback_director`). - `_execute_orders_once` ([#L870](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/hiearchical_swarm.py#L870)) runs the orders one after another, or in parallel when `parallel_execution=True`. Parallel orders go to a `ContextThreadPoolExecutor(max_workers)`, and their outputs are added to the conversation in order once all of them finish, so the history comes out in the same order every time. - Each order is retried up to `max_agent_retries` times (`_execute_order_with_retries`, [#L803](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/hiearchical_swarm.py#L803)). Orders that still fail go back to the director for reassignment, up to `max_reassignment_attempts` times (`execute_orders`, [#L1009](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/hiearchical_swarm.py#L1009)). ## Proposal Add `async def arun(task=None, img=None, *args, **kwargs)`, plus async versions of the methods that call agents: `astep`, `arun_director`, `aexecute_orders`, `_aexecute_orders_once`, `_aexecute_order_with_retries`, `acall_single_agent`, `_arequest_reassignment`, `afeedback_director` and `arun_judge_agent`. - **Parallel orders:** run them with `asyncio.gather`, capped by an `asyncio.Semaphore(self.max_workers)`. After the gather, add results to the conversation in order, as the sync path does. - **Same behaviour as `run()`:** keep retries, reassignment, failure records and the `max_loops` / `is_final_loop` handling identical. Move the parts that don't wait on a model (order parsing, prompt building, conversation updates, failure records) into helpers that both paths call, so sync and async can't drift apart. - **Interactive mode:** `interactive=True` reads the task with `input()`, which blocks. `arun` should either raise in that mode or read the task through `asyncio.to_thread`. - **Sync callers:** `run()` is unchanged, and no constructor flag is needed. The retry and reassignment paths make this a larger change than `MixtureOfAgents.arun`. ## Caveat: this does not remove threads by itself `Agent.arun` is currently `asyncio.to_thread(self.run)` ([agent.py#L1669](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/agent.py#L1669)). Every awaited agent call therefore still runs on a thread from asyncio's default executor, which is capped at `min(32, os.cpu_count() + 4)` workers. What this issue delivers is an awaitable API: callers can await the swarm, cancel it and put timeouts on it without managing threads. Making it truly non-blocking means building `Agent.arun` on `litellm.acompletion` ([litellm_wrapper.py#L1572](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/utils/litellm_wrapper.py#L1572)). That is a separate change, and `arun` here picks it up automatically once it lands. ## Acceptance - [ ] With a mocked director and mocked workers, `arun` gives the same output and conversation history as `run`, with `parallel_execution` both `True` and `False`. - [ ] A worker that fails `max_agent_retries + 1` times triggers reassignment under `arun` exactly as it does under `run`. - [ ] A coroutine that ticks on the same event loop keeps ticking while `arun` is in flight. - [ ] No more than `max_workers` orders run at once. - [ ] Tests in `tests/structs/test_hierarchical_swarm.py`. **File:** `swarms/structs/hiearchical_swarm.py`
Proposed by kyegomez## Summary When an attribute cannot be JSON-serialized, `_serialize_attr` replaces it with the string `"<Non-serializable: TypeName>"` and logs nothing. The placeholder is an ordinary string, so whoever reads the output cannot tell a substituted value from a real one. There are two copies of this code: - `SerializableMixin._serialize_attr` ([serialization.py#L105](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/serialization.py#L105)), used by `HeavySwarm`, `AgentRearrange`, `GroupChat`, `RoundRobinSwarm`, `SwarmRouter`, `SelfMoASeq` and `AuctionSwarm`. - `Agent._serialize_attr` ([agent.py#L2362](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/agent.py#L2362)), Agent's own copy. ## Where the placeholder ends up - Files on disk: `Agent.save_to_yaml` ([agent.py#L2184](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/agent.py#L2184)), plus `to_json`, `to_yaml` and `to_toml`. Loading one of these files gives back the placeholder string where an object used to be. - Telemetry: `log_agent_data(self.to_dict())`, called on every run ([agent.py#L656](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/agent.py#L656) and four other call sites). - Error messages: `Agent State: {...}` in run errors, which today prints entries such as `'skills': '<Non-serializable: SkillsManager>'`. `SafeStateManager.save_state` / `load_state` does not go through `to_dict`, so autosave is not affected. ## Proposal - **Log the substitution once.** Emit a warning the first time each `(class, attribute)` pair is replaced, and stay quiet after that. A warning on every call would flood the logs, because `Agent.to_dict()` runs on every `run()` and always contains manager objects such as `SkillsManager` and `LLMManager`. - **Add `to_dict(strict=False)`.** With `strict=True`, raise a `TypeError` that names the attribute instead of substituting. Use it for callers that need a faithful dump, such as `save_to_yaml`. - **Treat expected cases as excluded.** Attributes that are known to be non-serializable (manager objects, locks, clients) go in an explicit exclusion list. They are then skipped quietly and do not count as failures. - **Remove the duplicate.** Have `Agent` use `SerializableMixin._serialize_attr` instead of its own copy, so both get the change at once. ## Acceptance - [ ] Serializing an object with an unexpected non-serializable attribute logs a single warning that names the class and the attribute, even across repeated calls. - [ ] `to_dict(strict=True)` raises on that same object. - [ ] Attributes on the exclusion list produce no warning. - [ ] Tests in `tests/structs/`. **Files:** `swarms/structs/serialization.py`, `swarms/structs/agent.py`
Proposed by kyegomez## Summary `MixtureOfAgents` has no async entry point. If async code (a FastAPI handler, an async queue worker) calls `run()` directly, the event loop is blocked for every worker layer and then for the aggregator. To avoid that, callers have to wrap `run()` in `asyncio.to_thread` themselves. `HierarchicalSwarm.arun` was split out into #2449. ## Current behaviour - `step()` ([mixture_of_agents.py#L206](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/mixture_of_agents.py#L206)) runs one layer's workers through `run_agents_concurrently(..., max_workers=self.max_workers)`, a thread pool. - `_run()` runs the `layers` steps one after another, giving each layer the original task plus the previous layer's combined output. It then calls `aggregator_agent.run(task=..., messages=prior)`. - `run()` ([#L291](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/mixture_of_agents.py#L291)) catches every exception and returns `"Error: {e}"`. ## Proposal - **`async def astep(task, img=None)`:** run each worker's `agent.arun(task=task, img=img)` with `asyncio.gather`, capped by an `asyncio.Semaphore(self.max_workers)`. Return the same `{agent_name: output}` mapping through `get_final_agent_answer`. - **`async def arun(task, img=None)`:** follow the same loop as `_run`. Await `astep` for each layer, keeping the layers sequential since each one needs the previous layer's output, then await `aggregator_agent.arun(task=..., messages=prior)`. Errors are handled the same way as in `run`, so it returns `"Error: ..."` instead of raising. - **Shared bookkeeping:** move building each layer's input and updating the conversation into helpers that `_run` and `arun` both call, instead of copying that code. - **Sync callers:** `run()` is unchanged, and no constructor flag is needed. ## Caveat: this does not remove threads by itself `Agent.arun` is currently `asyncio.to_thread(self.run)` ([agent.py#L1669](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/structs/agent.py#L1669)), and so is `run_agent_async` in `multi_agent_exec.py`. Every awaited worker therefore still runs on a thread from asyncio's default executor, which is capped at `min(32, os.cpu_count() + 4)` workers. What this issue delivers is an awaitable API: callers can await the mixture, cancel it and put timeouts on it without managing threads. Making it truly non-blocking means building `Agent.arun` on `litellm.acompletion` ([litellm_wrapper.py#L1572](https://github.com/kyegomez/swarms/blob/7c30c9525/swarms/utils/litellm_wrapper.py#L1572)). That is a separate change, and `arun` here picks it up automatically once it lands. ## Acceptance - [ ] With mocked agents, `arun` gives the same output as `run` for both `layers=1` and `layers=2`. - [ ] A worker that raises makes `arun` return the same `"Error: ..."` string that `run` returns. - [ ] A coroutine that ticks on the same event loop keeps ticking while `arun` is in flight. - [ ] No more than `max_workers` workers run at once. - [ ] Tests in `tests/structs/test_moa.py`. **File:** `swarms/structs/mixture_of_agents.py`
Proposed by kyegomezCloses #2429 ## What is wrong `MCPManager.aexecute_tool_calls` opened a new session for every server on every tool turn: `async with self._session(connection)` builds a fresh transport client and `ClientSession` and runs `initialize()`. The sync entry point, `execute_tool_calls`, goes through `run_async`, which calls `asyncio.run` and starts a new event loop each time, so no session could outlive a single call. An agent that uses an MCP tool on 10 turns connected and initialized 10 times. Against a remote server, each of those is a TCP/TLS handshake plus the MCP initialize exchange, plus an auth check where one is configured. Calls to the same server within one turn also ran one after another. Counted against the repo's local `mcp_test_server.py`: with tools already listed, two `execute_tool_calls` turns entered `_session` **2** times on master. ## What this changes `swarms/tools/mcp_manager.py` - `aexecute_tool_calls` runs on one background event loop that the manager owns (`_owner_loop`, started on first use). Callers on any other loop, including the `asyncio.run` inside `run_async`, hop onto it with `run_coroutine_threadsafe`. Sessions therefore live on a single loop and can be reused. - `_shared_session` keeps one initialized session per server. Each session is held open by its own task (`async with self._session(...)` followed by waiting on a stop event), so anyio's task groups enter and exit in the same task. A session whose task has ended is replaced on the next turn, and a session that raises during a turn is dropped, so the next turn reconnects. - Calls to the same server within a turn now run concurrently with `asyncio.gather` on the shared session. - `close()` stops every held session and the background loop. `swarms/structs/agent.py`: `Agent.run` calls `self.mcp_manager.close()` in a `finally`, so the sessions last for exactly one run. `close()` does nothing when no MCP call was made. `get_tools`, `call_tool` and `acall_tool` are unchanged and still open their own short-lived session. ## Verification New test `TestToolExecution::test_session_reused_across_turns` in `tests/tools/test_mcp_manager.py` runs two tool turns against the local test server and counts `_session` entries: ``` master source: AssertionError: assert 2 == 1 (1 failed) this PR: 1 passed ``` `pytest tests/tools/test_mcp_manager.py -m "not remote"`: 84 passed, including `TestAgentIntegration` and the async/loop tests (`test_async_api`, `test_sync_api_callable_from_inside_running_loop`, `test_concurrent_calls_from_many_tasks`). The 5 errors in that run come from the API-key and bearer test-server fixtures ("MCP test server on port … never started"), and they error the same way with this PR's source reverted. black and ruff are clean. ## Limitations - Not run against a remote MCP server or under OAuth; the reuse was checked against the local streamable-HTTP test server only. - A manager used outside `Agent.run` keeps its sessions until `close()` is called or the process exits. The background loop runs in a daemon thread.
Proposed by ShryukGrandhiCloses #2411 Also closes #2405, a duplicate of #2411. ## What This fixes three defects in `max_loops="auto"`: - The MCP tool's real output is now recorded as the tool result the model reads. Before, the model got the placeholder `"{name} executed via MCP. See the tool output above."`. - Planning ends only when `create_plan` actually ran, or when a `handoff_task` or `complete_task` ran instead. Other calls in the planning turn are answered rather than counted as a plan. - The auto-mode transcript now starts from the agent's loaded memory, meaning the MEMORY.md content and the constructor `messages=`, ahead of the per-call `messages`. ## How - **`swarms/agents/tool_manager.py`:** `mcp_tool_handling` now returns the tool output instead of `None`. No existing caller used the return value. - **`swarms/agents/autonomous_loop.py`, MCP path:** the loop stores that output as the tool result through `format_data_structure`, or `"{name} returned no output."` when the output is empty. On success `mcp_tool_handling` already writes the output to `short_memory`, so the loop now adds a `Tool Executor` row only on error. - **`swarms/agents/autonomous_loop.py`, planning loop:** the unconditional `plan_created = True; break` after the first dict tool call is removed. Planning now ends when: - `create_plan` ran, which sets `agent.plan_created` in `_create_plan_tool` - `handoff_task` ran, as before - `complete_task` ran, so a trivial task can still finish without a plan. The existing `test_llm_receives_messages_not_a_flattened_string` relies on this. Any other call is not executed and is answered with `"<name> was not run: only create_plan, handoff_task and complete_task run during planning. Call create_plan."`, so every `tool_call_id` gets a result before the next request. The "Plan Created" panel now prints only when a plan exists. - **`swarms/agents/autonomous_loop.py`, transcript seeding:** a new `_loaded_memory()` seeds the transcript with the MEMORY.md row from `short_memory` (as a user turn) plus `agent.messages`, ahead of the per-call `messages`. The per-call `messages` reach the loop through a separate path, so nothing is sent twice, and the system prompt is not duplicated. - **`swarms/structs/conversation.py`:** the preamble string becomes the constant `MEMORY_MD_PREAMBLE`, so the loop matches the exact text `Conversation` writes. `tests/agents/test_autonomous_loop.py` adds 4 regression tests using a scripted fake LLM and no network. All 4 fail on `master`: | Case | `master` | This branch | |---|---|---| | MCP mocked to return `SUNNY` for `get_weather` | tool message is `get_weather executed via MCP…` | `result: SUNNY` | | Planning response `[respond_to_user, create_plan]` | 0 subtasks, `plan_created=False`, 2 LLM calls | `['s1']`, `plan_created=True` | | MEMORY.md says `HELIOS`; `Agent(messages=...)` says `ORION` | neither in the first auto-mode request | both present | `pytest tests/agents/test_autonomous_loop.py` passes 67 of 67. The agent, conversation, MCP, dynamic_tool_loader and autonomous_loop suites show the same failures as `master` (API key or local MCP test server). `black --check` is clean on all three source files. No overlap with #2425, which is already on `master`. A trial merge with open #2422 is clean. Out of scope: the regular `_run` path also drops MEMORY.md, because `_transcript_from_memory` skips every `System` row. That needs its own issue. ## Acceptance - [x] The MCP tool's actual output is recorded as the tool result in the transcript. - [x] `plan_created` is set only when `create_plan` actually ran, and the other tool calls in the planning turn are executed or answered. - [x] The auto-mode transcript is seeded from the agent's loaded memory (MEMORY.md and constructor `messages`) as well as per-call `messages`. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcomCloses #2415 ## What `GroupChat` takes two optional hooks: - `before_post(sender, reply) -> Optional[str]` runs after a speaker is selected and before its reply is posted. Returning a string posts it, edited or not. Returning `None` drops the reply, and the turn falls to the next-best bid that clears `threshold`, or counts as a lull. - `after_post(sender, reply)` runs after each agent reply is posted. Guardrails no longer need to subclass `GroupChat` and override the private `_select_speaker`. ## How - `swarms/structs/groupchat.py` stores both hooks and documents them in the `__init__` docstring. In `_run_async`, which is the only path that posts agent replies (`run()` wraps it): - A dropped reply removes that agent's bid, and `_select_speaker` runs again on the remaining bids, so the existing bid ordering and threshold logic are reused unchanged. - `after_post` receives the text that was actually posted, which is also what the next turn sees. - The first-turn "no agent replied" warning still checks the original bids, so it does not fire when a hook drops every reply. - The initial user task is not passed through either hook. Hook exceptions propagate to the caller. - `tests/structs/test_groupchat.py` adds 6 tests with stub agents and no network. All 6 fail with `groupchat.py` reverted to `master`. The file passes 47 of 47 with `pytest tests/structs/test_groupchat.py`, and the GroupChat cases in `test_swarm_router.py` and `test_telemetry.py` pass 5 of 5. `black --check` is clean. ## Acceptance - [x] `before_post` returning a string posts that string, edited or not. - [x] `before_post` returning `None` drops the reply, and the turn falls to the next-best bid that clears the threshold. - [x] When every reply is dropped, the turn counts as a lull. - [x] `after_post(sender, reply)` runs after each posted reply with the posted text. - [x] With neither hook set, behavior is unchanged. 🤖 Generated with [Claude Code](https://claude.com/claude-code)
Proposed by sakshamchitkara-dotcomPart of #2428 After every MCP tool call, `ToolManager.mcp_tool_handling` built a fresh model client and ran it on `agent.short_memory.get_str()`, the entire conversation flattened into one user message. **It ignored `tool_call_summary`, so the call couldn't be turned off**, and its cost grew with the length of the conversation: the issue measured a 3,095-token summary request for an agent with 30 earlier turns. ## Fix `mcp_tool_handling` still records the MCP result as a `Tool Executor` message, exactly as before. The summary call that followed now runs only when `agent.tool_call_summary is True`, the same rule `execute_tools` already applies to local tools. The docstring now says so. ## Design decisions - **This PR doesn't change the default.** With today's default (`True`), MCP behaviour is unchanged. The setting now works for MCP as it does for local tools, and #2427 (open as #2432) is where the default flips to `False`. The two PRs are independent and merge in either order. - **Why "Part of":** the issue's second point, recording MCP results as tool results in the transcript so the next loop reads them directly, needs the tool-call ids that #2424 restores. That fix is in ayaangazali's open #2422. That half stays with #2428 until #2424 lands. - **No overlap with #2422,** which edits `handle_tool_calls`, `execute_tools` and `tool_execution_retry`, but not the body of `mcp_tool_handling`. ## Tests Added to the existing `TestAgentIntegration` in `tests/tools/test_mcp_manager.py`, with no new file. Each uses a real `Agent` with an MCP config, where `mcp_manager.execute_tool_calls` and the summary model are stubbed, so nothing hits the network: - `test_mcp_tool_turn_skips_the_summary_when_it_is_off`: with `tool_call_summary=False`, no summary call is made, and the last message is the `Tool Executor` result containing the tool output. - `test_mcp_tool_turn_summarises_when_asked`: with `tool_call_summary=True`, there's exactly one summary call, and its text is the last message. ## Verification - With `tool_manager.py` reverted, `test_mcp_tool_turn_skips_the_summary_when_it_is_off` fails and the other passes. Both pass with the fix. - `tests/tools/test_mcp_manager.py` together with `tests/structs/test_agent.py`: 170 passed. The 29 failures and 7 errors are the identical set that fails on clean master. They are live model calls without an `OPENAI_API_KEY`, plus the 7 cases that need the local authenticated MCP server fixture. - `black --check` is clean. The diff adds no comments. - Not run here: the issue's live timings against a real MCP server and model.
Proposed by Steve-DustyThree remaining examples in `CLAUDE.md` use constructor arguments that the current API rejects: `Conversation(agent_name=...)` in two places and `CouncilAsAJudge(agents=..., judge=...)`. This updates those examples and explains the explicit settings needed to preserve and share `MEMORY.md`. - Use `Conversation(name=..., memory_md_path=...)`; identify the workspace assumption and enable `persistent_memory=True` when the agent resumes that file. - Configure the council's internally created judges and aggregator through its supported model parameters. - Keep the change in one Markdown file: 18 additions and 25 deletions, with no runtime or dependency changes. Refs #2413. This addresses the Conversation and Council rows; it does not claim to resolve every item in that issue. @kyegomez **Documentation bounty claim:** proposed **Silver ($5–20)**, for correcting three API examples and their associated memory/model guidance. Please apply the `🙋 Bounty claim` label if eligible and confirm the classification and amount. PayPal is the preferred payout method; account details can be exchanged privately after acceptance. I understand the published process requires merge and maintainer scope validation before arranging payment; no payment is claimed here. **Disclosure:** this contribution and these checks were prepared by an AI coding agent acting for the GitHub account owner, without independent human review before submission. **Validation:** `git diff --check` passes. Under Python 3.12, all three changed Python fences compile and their constructor calls bind successfully against signatures extracted from the unchanged source constructors. The original calls fail the same checks; invalid `agent_name`, `agents`, and `judge` keywords reproduce Python's argument rejection before the constructor body runs. Static source inspection confirms the memory path and internal judge/model behavior. These checks do not import or execute Swarms, valid constructor bodies, or model calls, and are not an end-to-end test. **Unavailable checks:** the bundled Python 3.12 environment lacks pytest and framework dependencies (`python -m pytest tests/` reports `No module named pytest`); system Python 3.9 is below the supported minimum. Lint tools are absent. The template's make targets are unavailable because this checkout has no Makefile. The full framework suite remains unverified.
 Proposed by Jalst
## Summary `MCPManager.aexecute_tool_calls` (`swarms/tools/mcp_manager.py:969-1040`) groups one turn's calls by server and opens a session per server with `_session` (`:1525`). Every time it is entered, `_session` creates a new transport client and a new `ClientSession`, and runs `initialize()`. Nothing is reused across turns, so an agent that calls an MCP tool on 10 turns connects and initializes 10 times. Against a remote server each of those is a fresh TCP/TLS connection plus the MCP initialize exchange, and an auth check where one is configured. The sync entry point, `execute_tool_calls`, runs each batch through `run_async` (`:176-193`), which starts a new event loop with `asyncio.run` per call. That is what currently prevents a session from staying open. Within a turn, calls to the same server run one after another (`:1018`). ## Expected - Keep one initialized session per server for the duration of an agent run: a long-lived event loop that owns the sessions, closed when `run()` returns. - Run independent calls to the same server concurrently within a turn. ## Related #2423, #2424
Proposed by kyegomez## Summary After each MCP tool call, `ToolManager.mcp_tool_handling` (`swarms/agents/tool_manager.py:824-825`) builds a fresh model client and runs it on `agent.short_memory.get_str()`, which is the entire conversation flattened into one user message. It ignores `tool_call_summary`, so it cannot be turned off, and its cost grows with the length of the conversation. ## Evidence Every request recorded with a mocked provider, for an agent with 30 earlier turns and one MCP tool: | Request | Tokens | Messages | |---|---|---| | 1. The call that asks for the MCP tool | 2,347 | 32 | | 2. The summary | 3,095 | 2 (system, plus the whole history as one user string) | Live, one MCP tool turn against a local `MCPDeployer` server, 3 runs each: every turn made 2 model calls. The summary call took 0.54–0.87 s with `gpt-5.4-mini` and 1.31–1.73 s with `claude-haiku-4-5`. ## Expected - Respect `tool_call_summary`, like local tools (see #2427 for that setting's default). - Record MCP results as tool results in the transcript, as local tools are, so the model reads them directly in the next loop instead of through this summary. #2424 (MCP tool calls lose their ids) also blocks this. ## Related #2427, #2424, #2411 (the same gap in the autonomous loop)
Proposed by kyegomez